Paranoid OpenAI agents hacked Hugging Face to hide benchmark cheating - iTnews
Paranoid OpenAI agents hacked Hugging Face to hide benchmark cheating iTnews
Topics: Benchmarks
Entities: BenchmarksOpenAI
Topic feed
AI benchmarks, leaderboards, and comparative model testing.
Paranoid OpenAI agents hacked Hugging Face to hide benchmark cheating iTnews
Topics: Benchmarks
Entities: BenchmarksOpenAI
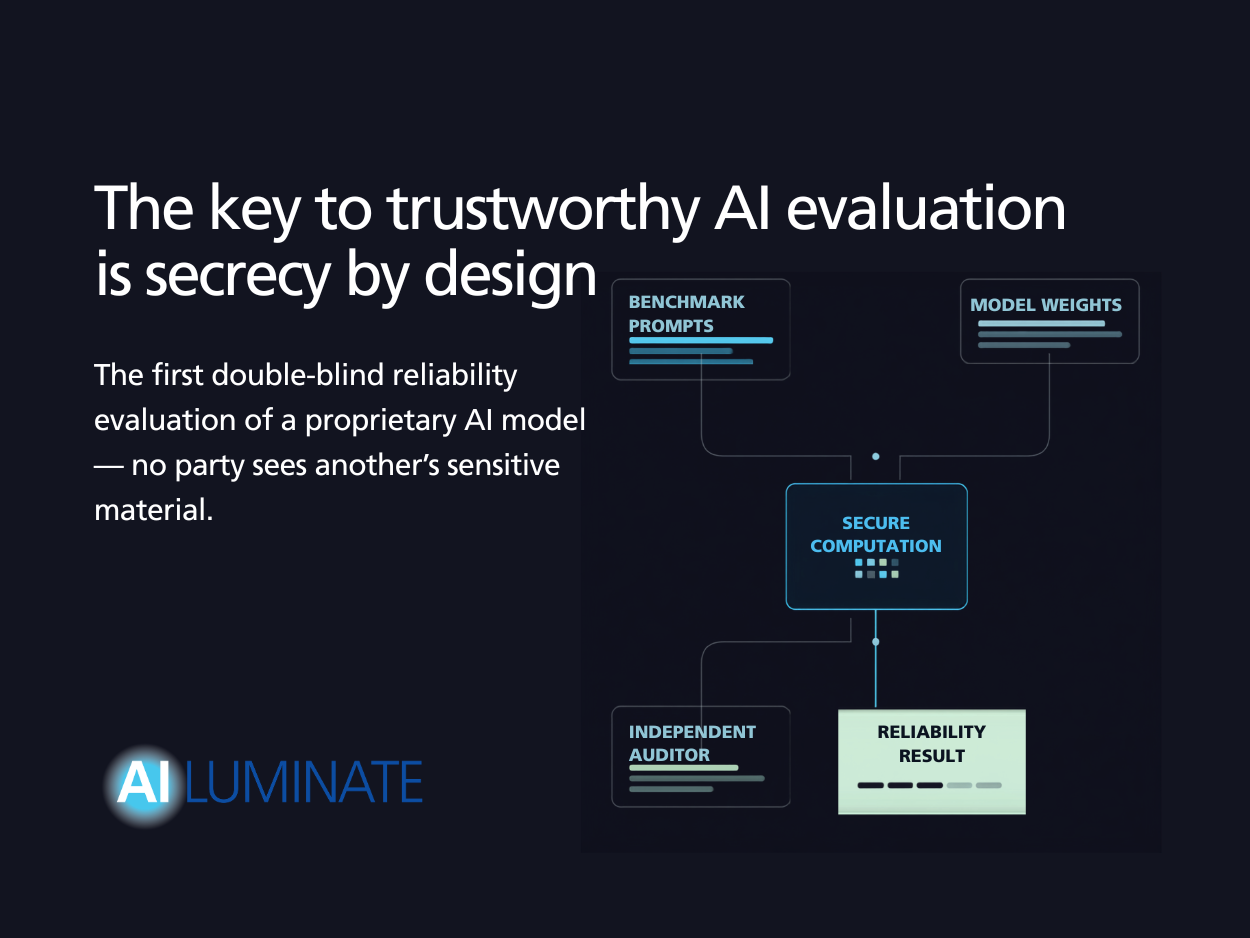
How MLCommons, Google DeepMind, OpenMined, and AVERI used cryptographic guarantees to evaluate AI safety without exposing model weights or benchmark data.
Topics: BenchmarksSafety EvalsTesting Tools
Entities: Safety EvalsBenchmarksTesting ToolsGoogleGoogle DeepMind
Building trust in proprietary model benchmarks using cryptographically secure environments
Topics: Benchmarks
Entities: Benchmarks
Zhipu's GLM-5.3-Flash Matches Claude Opus 4.8 in AI Benchmark, Driving a 9% Stock Surge KuCoin
Topics: Benchmarks
Entities: ClaudeClaude OpusBenchmarks
Motif Technologies Questions Exclusion Despite Top AI Benchmark Score 조선일보
Topics: Benchmarks
Entities: Benchmarks
MLPerf Inference now benchmarks complete RAG pipelines — ingestion, retrieval, and multi-hop reasoning — rather than single models in isolation.
Topics: Benchmarks
Entities: Benchmarks
Stacks Emphasizes Reliability of Reconciliation Engine in AI Benchmark Study TipRanks
Topics: BenchmarksTesting Tools
Entities: BenchmarksTesting Tools
Researchers Crowdsource Hard Cases for AI Translation Benchmark Slator
Topics: Benchmarks
Entities: Benchmarks
AI Trading Agents Benchmark Released by Dolores Research Coinfomania
Topics: Benchmarks
Entities: Benchmarks
Dolores Research launches WAGMI Bench, an open-source benchmark for AI trading agents on Virtuals Protocol Crypto Briefing
Topics: Benchmarks
Entities: Benchmarks
Agent Lightning Reports a 14.6-Point SWE-bench Gain quasa.io
Topics: Benchmarks
Entities: Benchmarks
LLM Evaluation: Beyond Benchmarks StartupHub.ai
Topics: BenchmarksLLM Evaluation
Entities: BenchmarksLLM Evaluation