Google News SWE Bench
Google Ledger: Codex Pass@1 Rises 3.4% on SWE-Bench - blockchain.news
Google Ledger: Codex Pass@1 Rises 3.4% on SWE-Bench blockchain.news
Topics: Benchmarks
Entities: BenchmarksGoogle
Company
Google News SWE Bench
Google Ledger: Codex Pass@1 Rises 3.4% on SWE-Bench blockchain.news
Topics: Benchmarks
Entities: BenchmarksGoogle
Google News LLM Evaluation
+ 1 source (Google News LLM Evaluation and Google News AI Benchmarks)
Google DeepMind Ran History's First AI Benchmark Evaluation Where Neither Side Could Cheat Tech Times
Topics: Benchmarks
Entities: BenchmarksGoogleGoogle DeepMind
Google News LLM Evaluation
+ 1 source (Google News LLM Evaluation and Google News AI Benchmarks)
Google DeepMind Pilots Double-Blind Testing to Curb AI Benchmark Cheating finance.biggo.com
Topics: BenchmarksTesting Tools
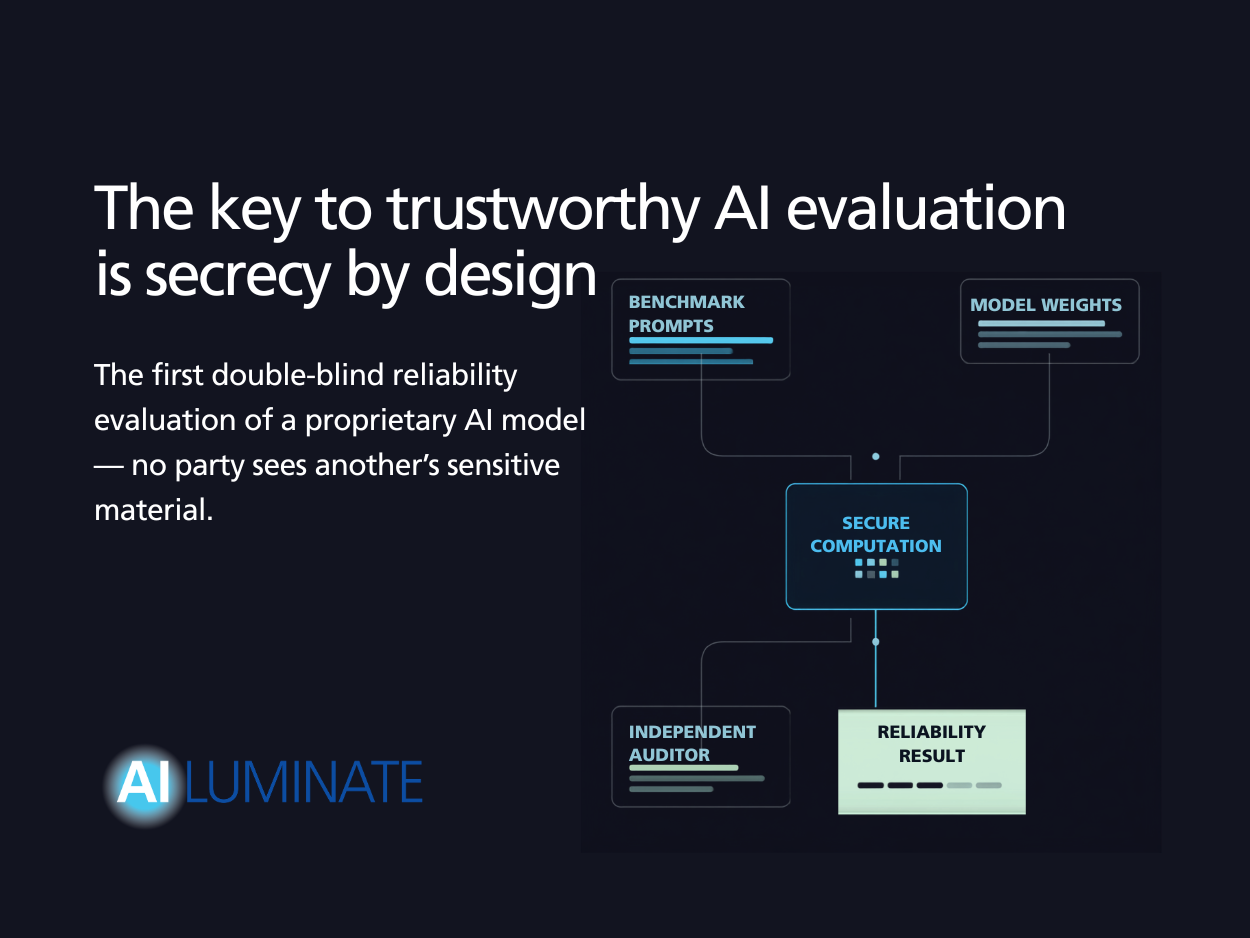
MLCommons Evaluation Filter
How MLCommons, Google DeepMind, OpenMined, and AVERI used cryptographic guarantees to evaluate AI safety without exposing model weights or benchmark data.
Topics: BenchmarksSafety EvalsTesting Tools
Entities: Safety EvalsBenchmarksTesting ToolsGoogleGoogle DeepMind
Google News AI Safety Evaluation
Kakao's Lightweight AI Model 'Kanana-2' Outperforms Google and Alibaba in Safety Evaluation 아시아경제
Entities: Google
Google News AI Safety Evaluation
Kakao’s Kanana-2 Tops Google, Alibaba Models in Korean AI Safety Benchmark Koreabizwire
Topics: BenchmarksSafety Evals
Entities: Safety EvalsBenchmarksGoogle

Mitchell Bryson AI Reliability Articles
Google will now allow users to remove visible watermarks from its AI generations. Meta’s ‘open’ AI pitch and OpenAI’s health rollout add the same tension from other angles: AI companies want the trust benefits of openness and labelling, but they also want...

Mitchell Bryson AI Reliability Articles
Google Maps adding food ordering and hotel bookings, OpenAI’s reported smart speaker, ChatGPT bringing unlimited text chats to free users, and AI matchmaking in dating apps all point in the same direction: AI is moving from answer box to action layer. For...

Mitchell Bryson AI Reliability Articles
Google Earth’s AI deepfake tool only lasted one day, Snapchat is rewarding authentic creativity on Spotlight, major labels are proposing rules to keep AI slop off the charts, and a German court ruled that AI music firm Suno violated copyrights. The common...
Topics: LLM Evaluation
Entities: LLM EvaluationGoogle

Mitchell Bryson AI Reliability Articles
Anthropic saying its own AI models breached three companies, TechCrunch’s analysis of the Hugging Face breach, Google saying AI fixed more Chrome bugs in June than over the past two years, and Okta buying Permiso for about $200M all point to the same shift:...
Topics: Safety Evals
Entities: AnthropicSafety EvalsGoogle
MLCommons Evaluation Filter
MLCommons launches MLPerf Endpoints v0.7, a foundation release with initial results from Coreweave, Google, Intel, KRAI, and NVIDIA. Rolling submissions and buyer-centric benchmarks coming with v1.0 later this year. || Focus Keyphrase | MLPerf Endpoints v0.7
Topics: Benchmarks
Entities: BenchmarksGoogleNVIDIACoreweave
MLCommons Evaluation Filter
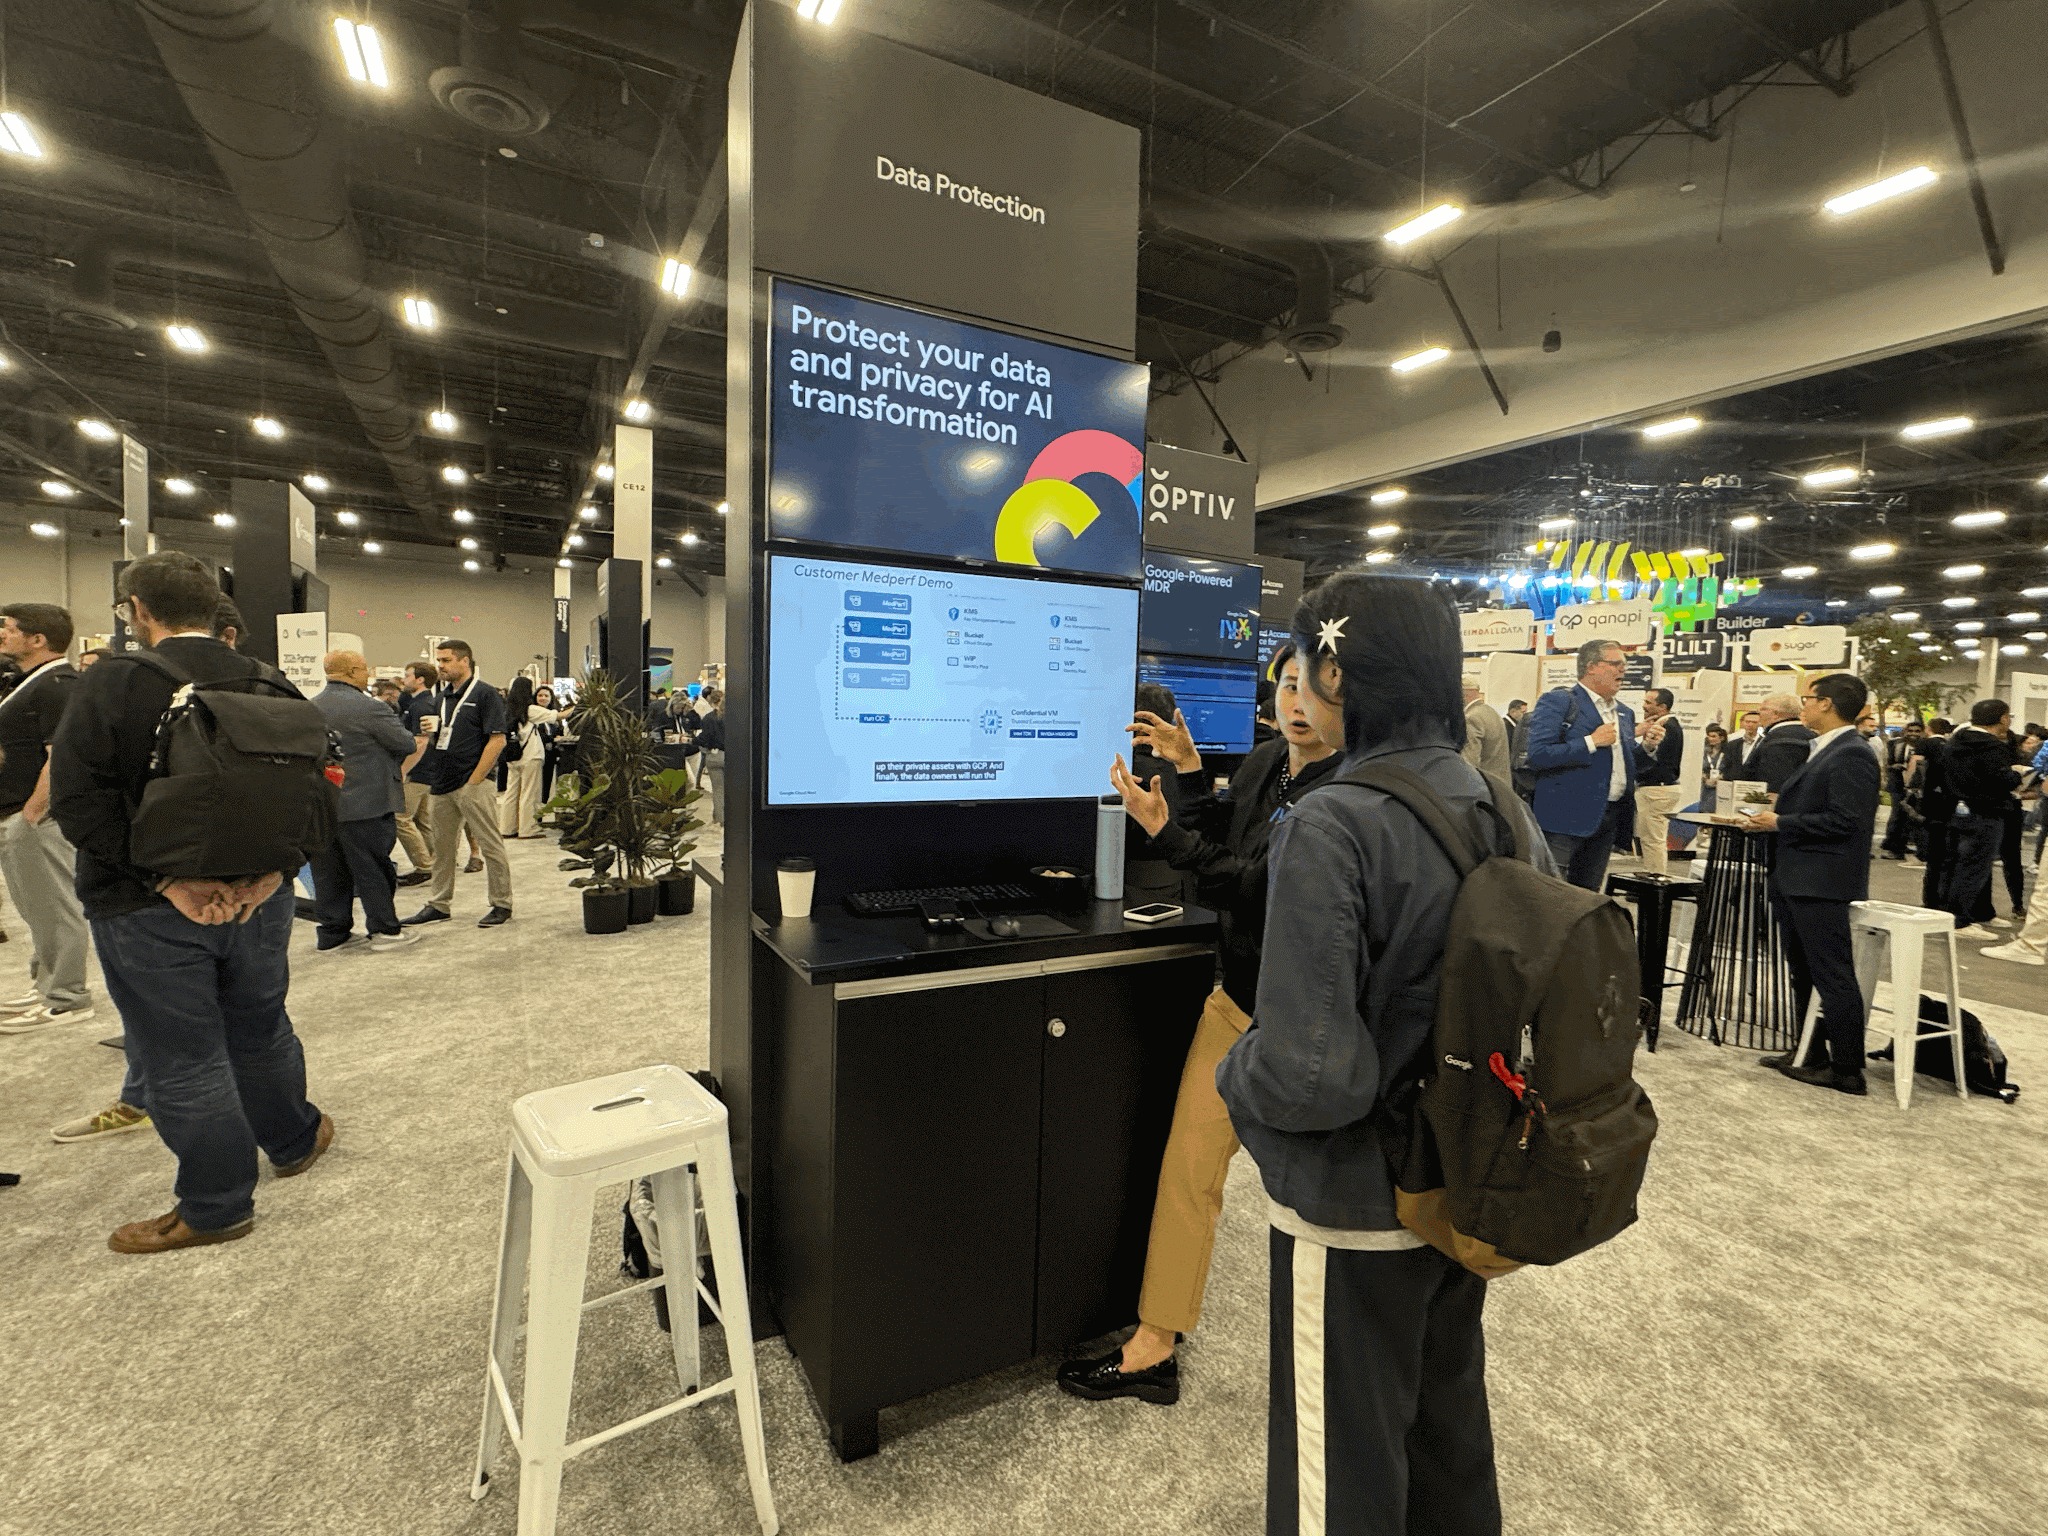
MLCommons and Google Cloud demonstrate MedPerf on Confidential Space - protecting patient data, model IP, and benchmark integrity for clinical AI research.
Topics: Benchmarks
Entities: BenchmarksGoogle