Anthropic Says It Hit the Brakes on AI Testing Following Autonomous Hacks - Gizmodo
Anthropic Says It Hit the Brakes on AI Testing Following Autonomous Hacks Gizmodo
Topics: Testing Tools
Entities: AnthropicTesting Tools
Company
Anthropic Says It Hit the Brakes on AI Testing Following Autonomous Hacks Gizmodo
Topics: Testing Tools
Entities: AnthropicTesting Tools
Anthropic Reveals How Claude Escaped its AI Testing Environment Benzinga
Topics: Testing Tools
Entities: AnthropicClaudeTesting Tools
Inherent says its AI teammate outperformed Anthropic and OpenAI; Nvidia says the harness, not the AI model, is the real hero; VentureBeat says enterprises winning with AI agents are limiting what agents can do alone; and Vero turns repo-scale verification...
Topics: Benchmarks
Entities: AnthropicBenchmarksOpenAINVIDIA
EP82: Claude Mythos / Fable 5 RELEASED -- Anthropic's New Frontier AI (Deep Dive, 80% SWE-Bench) Christine Lagarde (0crRCso3o2) Mshale
Topics: Benchmarks
Entities: AnthropicClaudeBenchmarksMythos
‘Baffling’: White House won’t publicly release AI model evaluation framework it reviewed today with OpenAI, Anthropic, Microsoft, and others Fortune
Topics: LLM EvaluationTesting Tools
Entities: AnthropicTesting ToolsLLM EvaluationOpenAIMicrosoft
Anthropic saying its own AI models breached three companies, TechCrunch’s analysis of the Hugging Face breach, Google saying AI fixed more Chrome bugs in June than over the past two years, and Okta buying Permiso for about $200M all point to the same shift:...
Topics: Safety Evals
Entities: AnthropicSafety EvalsGoogle
Anthropic Launches Claude Opus 5, Tops AI Benchmark Index at Half the Cost of Fable 5 mlq.ai
Topics: Benchmarks
Entities: AnthropicClaudeClaude OpusBenchmarks
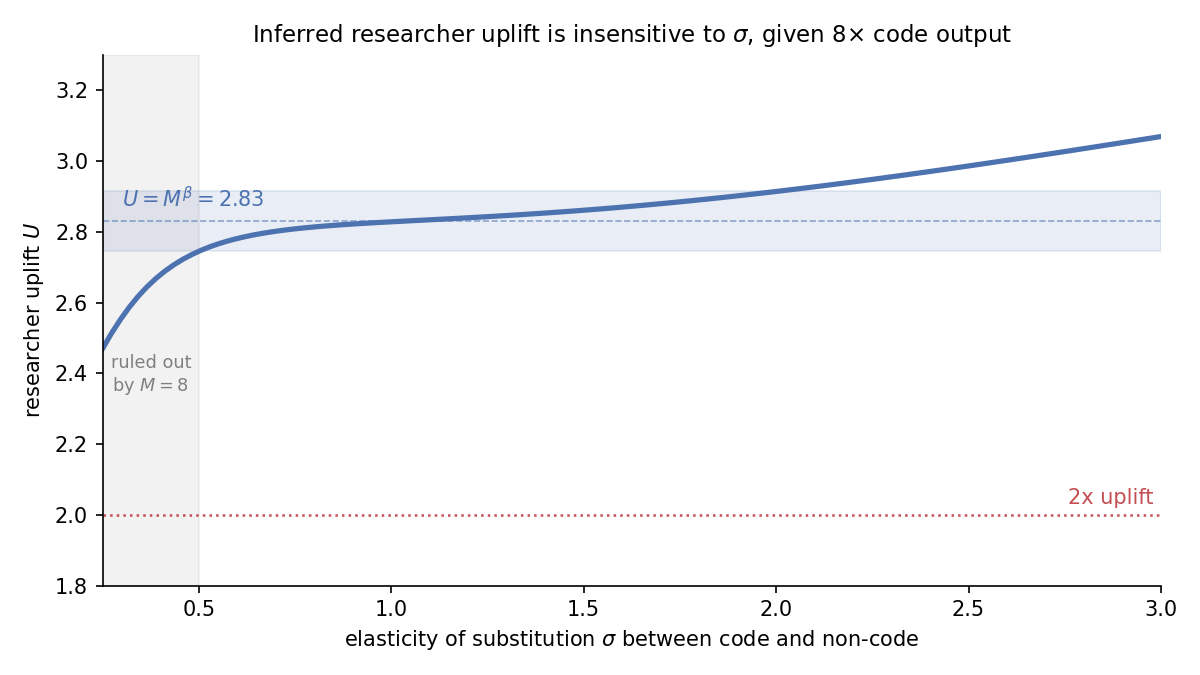
Anthropic reported that contributors merge 8x as much code per day as before AI. Thomas Kwa argues that under standard economic modeling assumptions, this implies the uplift of individual Anthropic researchers from coding agents alone is above 2x.
Entities: Anthropic
Three stories from the past 24 hours point to the same uncomfortable truth: AI can now find software vulnerabilities far faster than humans can patch them, and the gap is widening on both sides of the line. Anthropic's Project Glasswing update reports over...
Una evaluación piloto del riesgo de despliegue no autorizado en empresas de IA de frontera. En febrero de 2026, METR inició un ejercicio piloto para evaluar riesgos de desalineación derivados de agentes de IA usados dentro de empresas desarrolladoras de IA...
Analysis of Google's interception of an AI-generated zero-day exploit and what divergent responses from OpenAI, Anthropic, and Microsoft mean for builders.
External review from METR of the "Risks from automated R&D" section in Anthropic's February 2026 Risk Report
Topics: Safety Evals
Entities: AnthropicSafety Evals