 METR Blog
A simpler AI timelines model predicts 99% AI R&D automation in ~2032
Thomas Kwa describes a simple model for forecasting when AI will automate AI development, based on the AI Futures model but with only 8 parameters.
Source feed
116 items
METR is a research nonprofit that evaluates frontier AI models to inform the public about their risks and capabilities.
METR Blog
Thomas Kwa describes a simple model for forecasting when AI will automate AI development, based on the AI Futures model but with only 8 parameters.
METR Blog
Miles Kodama, Michael Chen y Garrett Xu resumen las disposiciones clave de la SB 53 de California, el Código de buenas prácticas de IA de uso general de la UE, la Ley RAISE de Nueva York y la SB 315 de Illinois que se aplican a desarrolladores de IA de...
METR Blog
Miles Kodama、Michael Chen 与 Garrett Xu 梳理了加州 SB 53、欧盟实践准则、纽约 RAISE 法案和伊利诺伊州 SB 315 的关键条款,说明前沿 AI 开发者需要关注哪些要求。
METR Blog
Miles Kodama and Michael Chen summarize key provisions from California's SB 53, the EU Code of Practice, and New York's RAISE Act covering frontier AI developers.
Topics: Safety Evals
Entities: Safety Evals
METR Blog
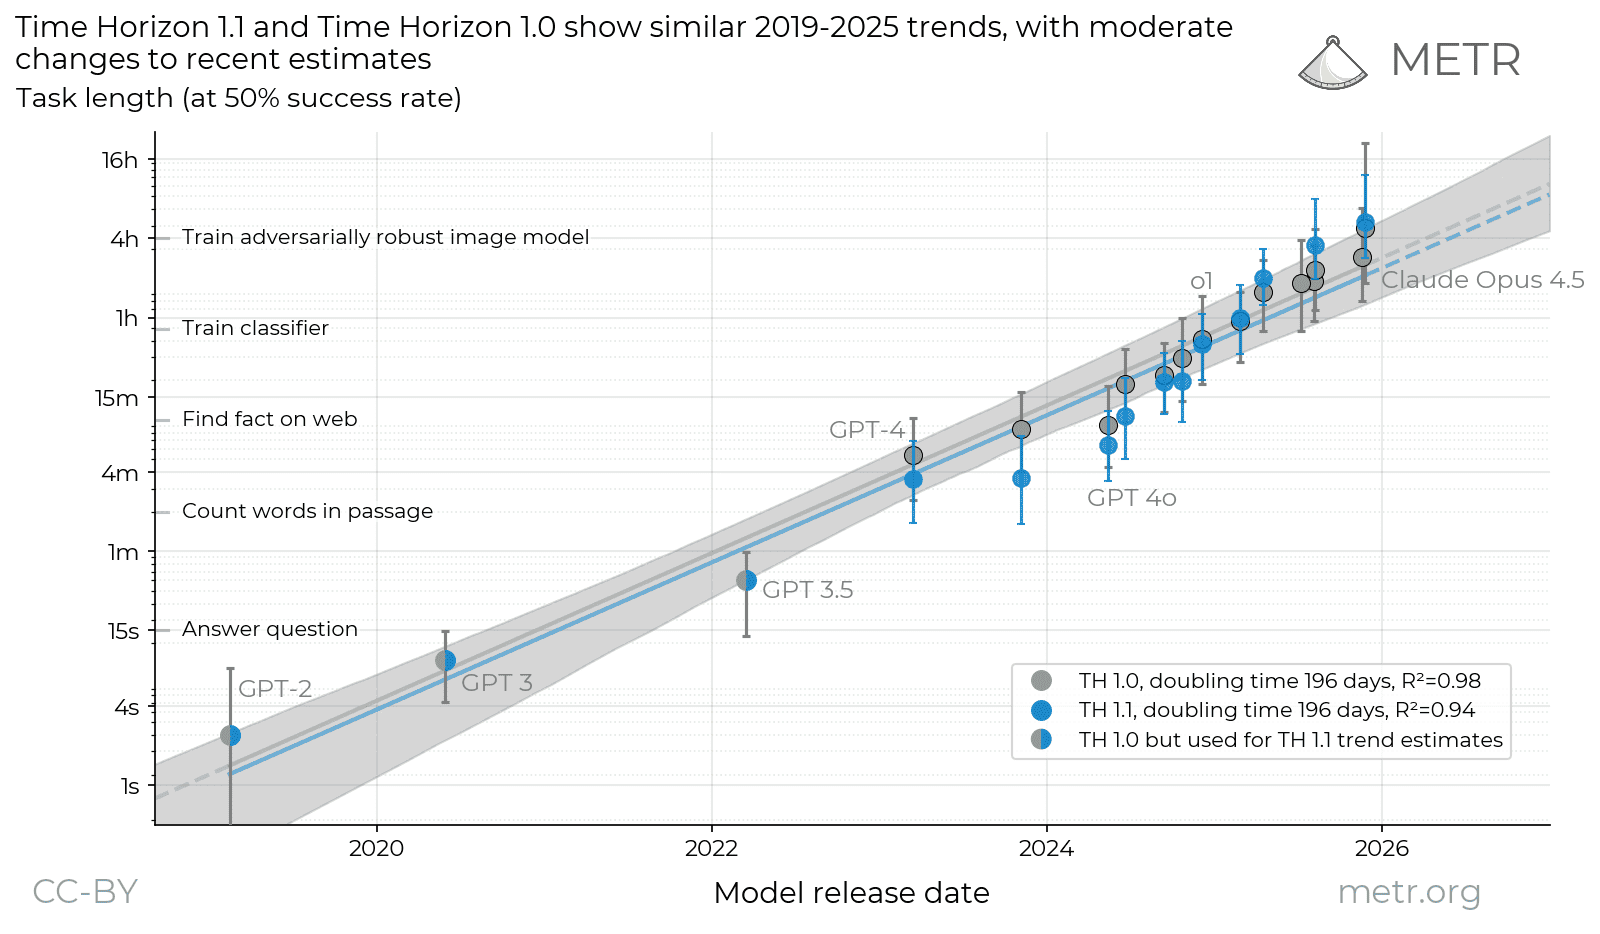
We’re releasing a new version of our time horizon estimates (TH1.1), using more tasks and a new eval infrastructure.
Topics: LLM Evaluation
Entities: LLM Evaluation
METR Blog
We’re releasing a new version of our time horizon estimates (TH1.1), using more tasks and a new eval infrastructure.
Topics: LLM Evaluation
Entities: LLM Evaluation
METR Blog
We show preliminary results on a prototype evaluation that tests monitors' ability to catch AI agents doing side tasks, and AI agents' ability to bypass this monitoring.
METR Blog
Thomas Kwa responds to some misinterpretations of our time horizon work, and explains limitations and the core finding.
METR Blog
Shared components of AI lab commitments to evaluate and mitigate severe risks.
Topics: Safety Evals
Entities: Safety Evals
METR Blog
We evaluate whether GPT-5.1-Codex-Max poses significant catastrophic risks via AI self-improvement, rogue replication, or sabotage of AI labs. We conclude that this seems unlikely.
Entities: OpenAI
METR Blog
External review from METR of Anthropic's Summer 2025 Sabotage Risk Report
Topics: Safety Evals
Entities: AnthropicSafety Evals
METR Blog
Details on external recommendations from METR for gpt-oss Preparedness experiments and follow-up from OpenAI.
Topics: Safety Evals
Entities: Safety EvalsOpenAI