METR Blog
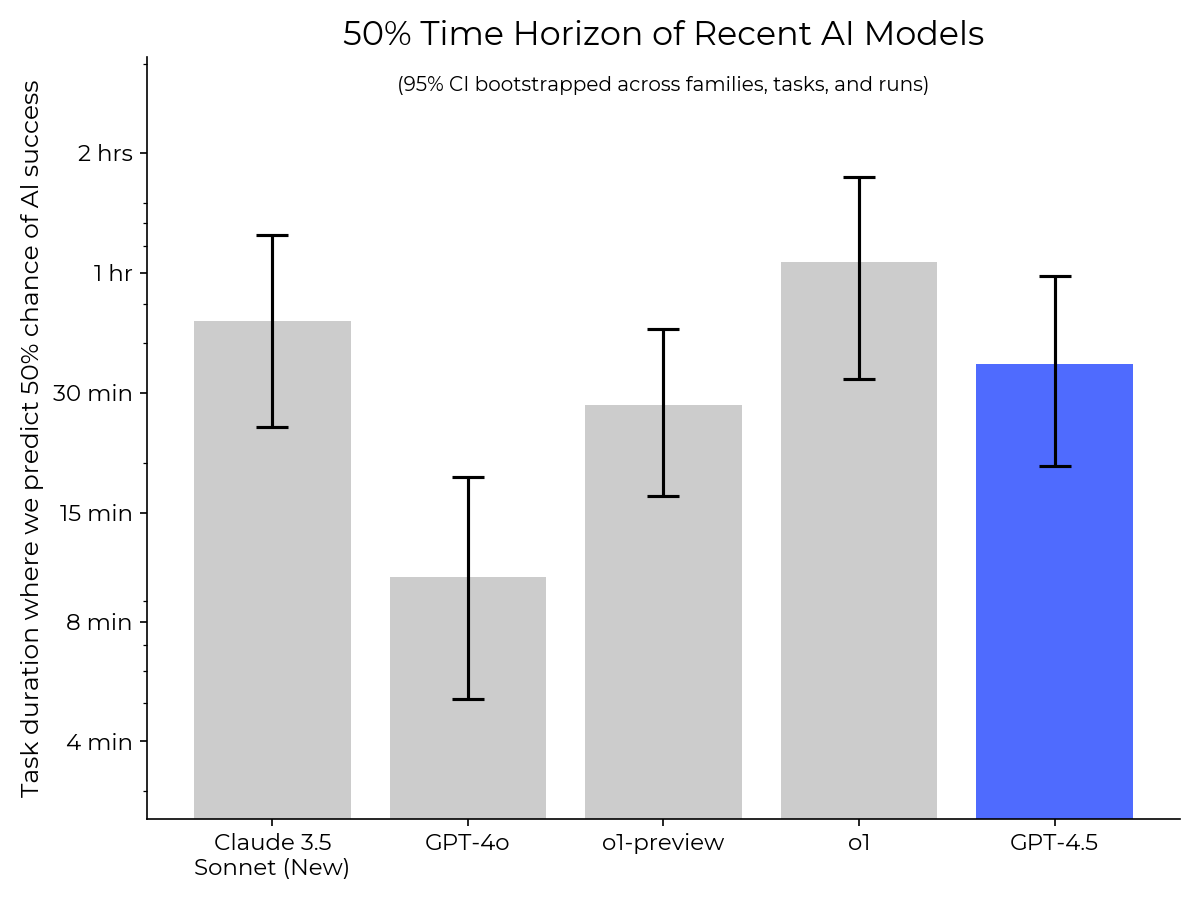
METR’s GPT-4.5 pre-deployment evaluations
Additional details about our evaluations of GPT-4.5, and some discussion about the limitations of pre-deployment evaluations and current evaluation methodologies.
METR Blog
Additional details about our evaluations of GPT-4.5, and some discussion about the limitations of pre-deployment evaluations and current evaluation methodologies.
METR Blog
We measured the performance of frontier models at writing GPU kernels. With a small amount of scaffolding, we found that the best model can provide an average speedup on KernelBench of 1.8x.
METR Blog
We evaluated DeepSeek-V3 for dangerous autonomous capabilities and found no evidence of dangerous capabilities beyond those of existing models such as Claude 3.5 Sonnet and GPT-4o. We also confirmed that its performance on GPQA is not due to training data...
Entities: Claude
METR Blog
Model Evaluation & Threat Research
Topics: Safety EvalsLLM Evaluation
Entities: Safety EvalsLLM Evaluation
METR Blog
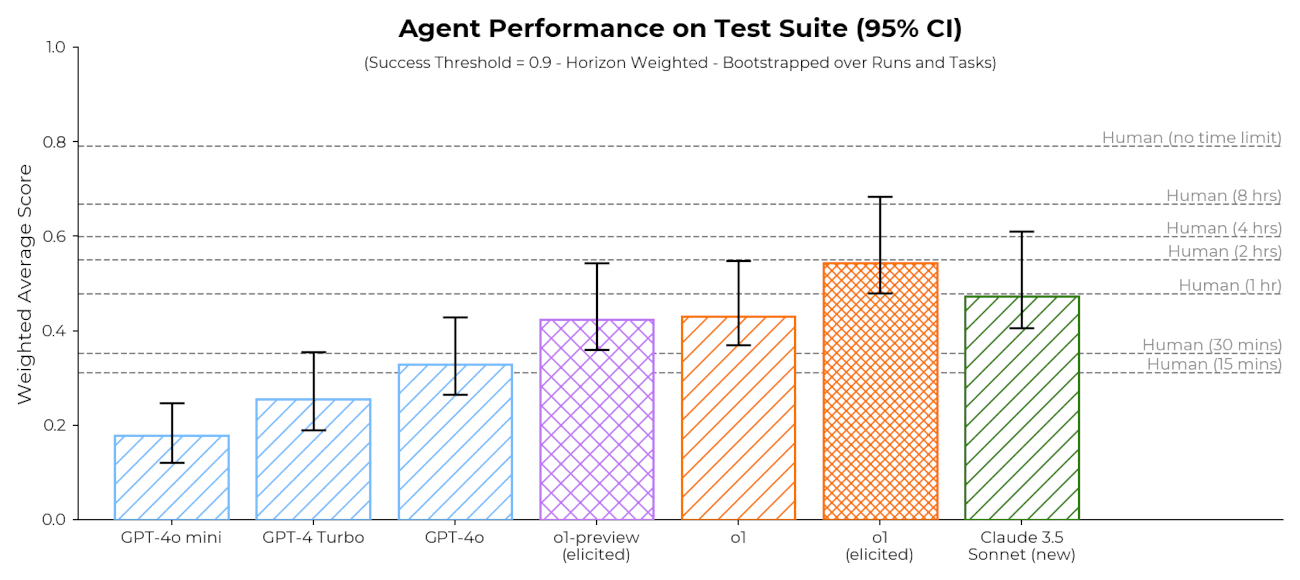
Preliminary evaluations of Claude 3.5 Sonnet (New) and o1, as well as some discussion of challenges in making capability-based safety arguments for AI models.
Entities: Claude
METR Blog
Why pre-deployment testing is not an adequate framework for AI risk management
Topics: Safety EvalsTesting Tools
Entities: Safety EvalsTesting Tools
METR Blog
We’re releasing RE-Bench, a new benchmark for measuring the performance of humans and frontier model agents on ML research engineering tasks. We also share data from 71 human expert attempts and results for Anthropic’s Claude 3.5 Sonnet and OpenAI’s...
Topics: Benchmarks
Entities: AnthropicClaudeBenchmarksOpenAI
METR Blog
Thoughts on how AI agents might develop large and resilient rogue populations.
METR Blog
Red-teaming and security suggestions regarding proposed rule by the Bureau of Industry and Security, “Establishment of Reporting Requirements for the Development of Advanced Artificial Intelligence Models and Computing Clusters.”
METR Blog
Funding for Canary will enable research and implementation at scale
METR Blog
We measured the performance of OpenAI's o1-mini and o1-preview models on our autonomy and AI R&D task suites, and found they did not exceed the capabilities of the best existing public model we've evaluated, though we could not confidently upper-bound their...
Entities: OpenAI
METR Blog
Suggestions for expanded guidance on capability elicitation and robust model safeguards in the U.S. AI Safety Institute’s draft document “Managing Misuse Risk for Dual-Use Foundation Models” (NIST AI 800-1).
Topics: Safety Evals
Entities: Safety Evals