MLCommons Releases New MLPerf Storage v3.0 Benchmark Results - MLCommons
Benchmark suite now covers the full range of AI workloads for storage systems
Topics: Benchmarks
Entities: Benchmarks
Benchmark suite now covers the full range of AI workloads for storage systems
Topics: Benchmarks
Entities: Benchmarks
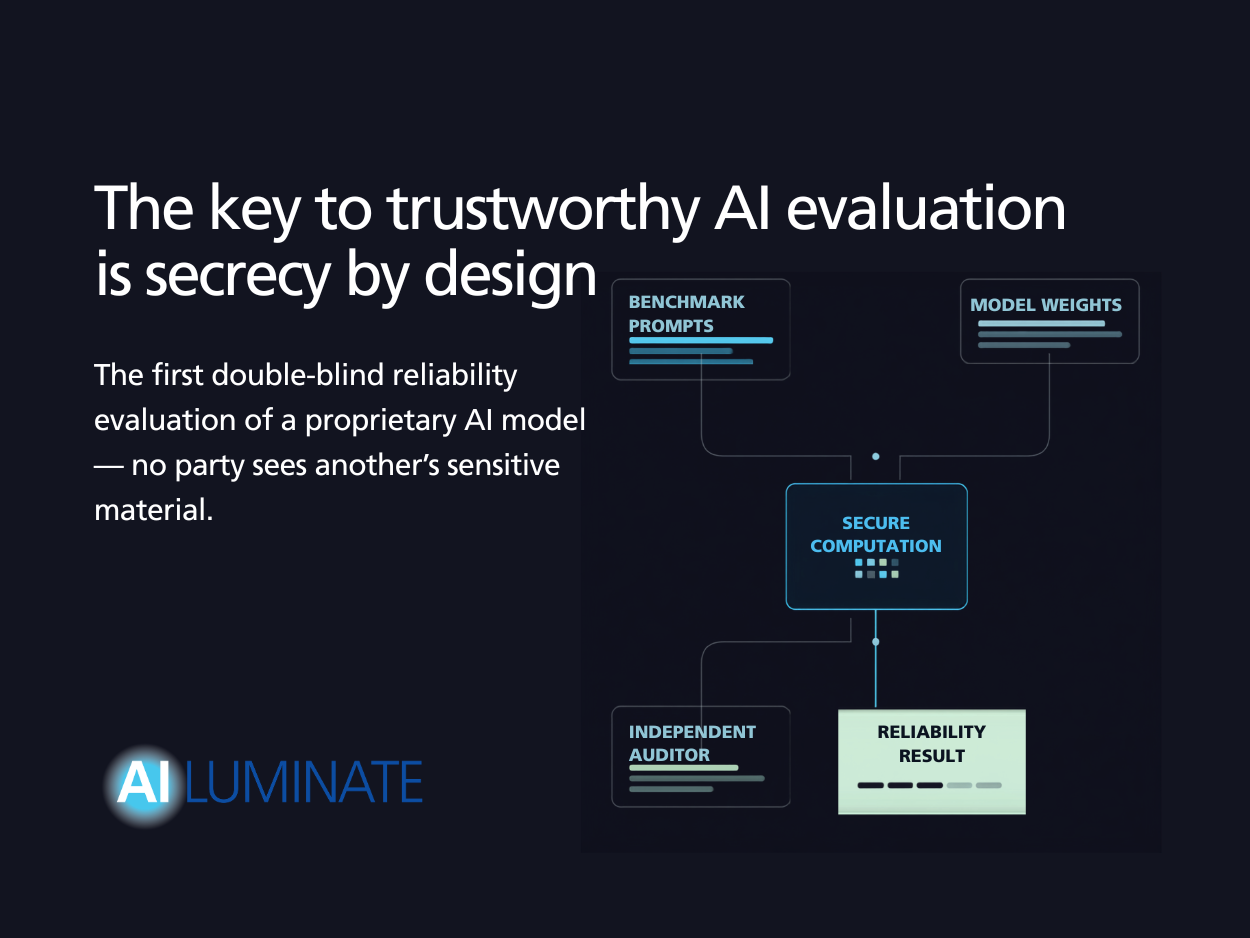
How MLCommons, Google DeepMind, OpenMined, and AVERI used cryptographic guarantees to evaluate AI safety without exposing model weights or benchmark data.
Topics: BenchmarksSafety EvalsTesting Tools
Entities: Safety EvalsBenchmarksTesting ToolsGoogleGoogle DeepMind
MLPerf Inference now benchmarks complete RAG pipelines — ingestion, retrieval, and multi-hop reasoning — rather than single models in isolation.
Topics: Benchmarks
Entities: Benchmarks
Meta description: How do you know if a benchmark result is trustworthy or just benchmark washing? MLCommons shares 7 questions every enterprise should ask before making a decision based on a benchmark score.
Topics: Benchmarks
Entities: Benchmarks
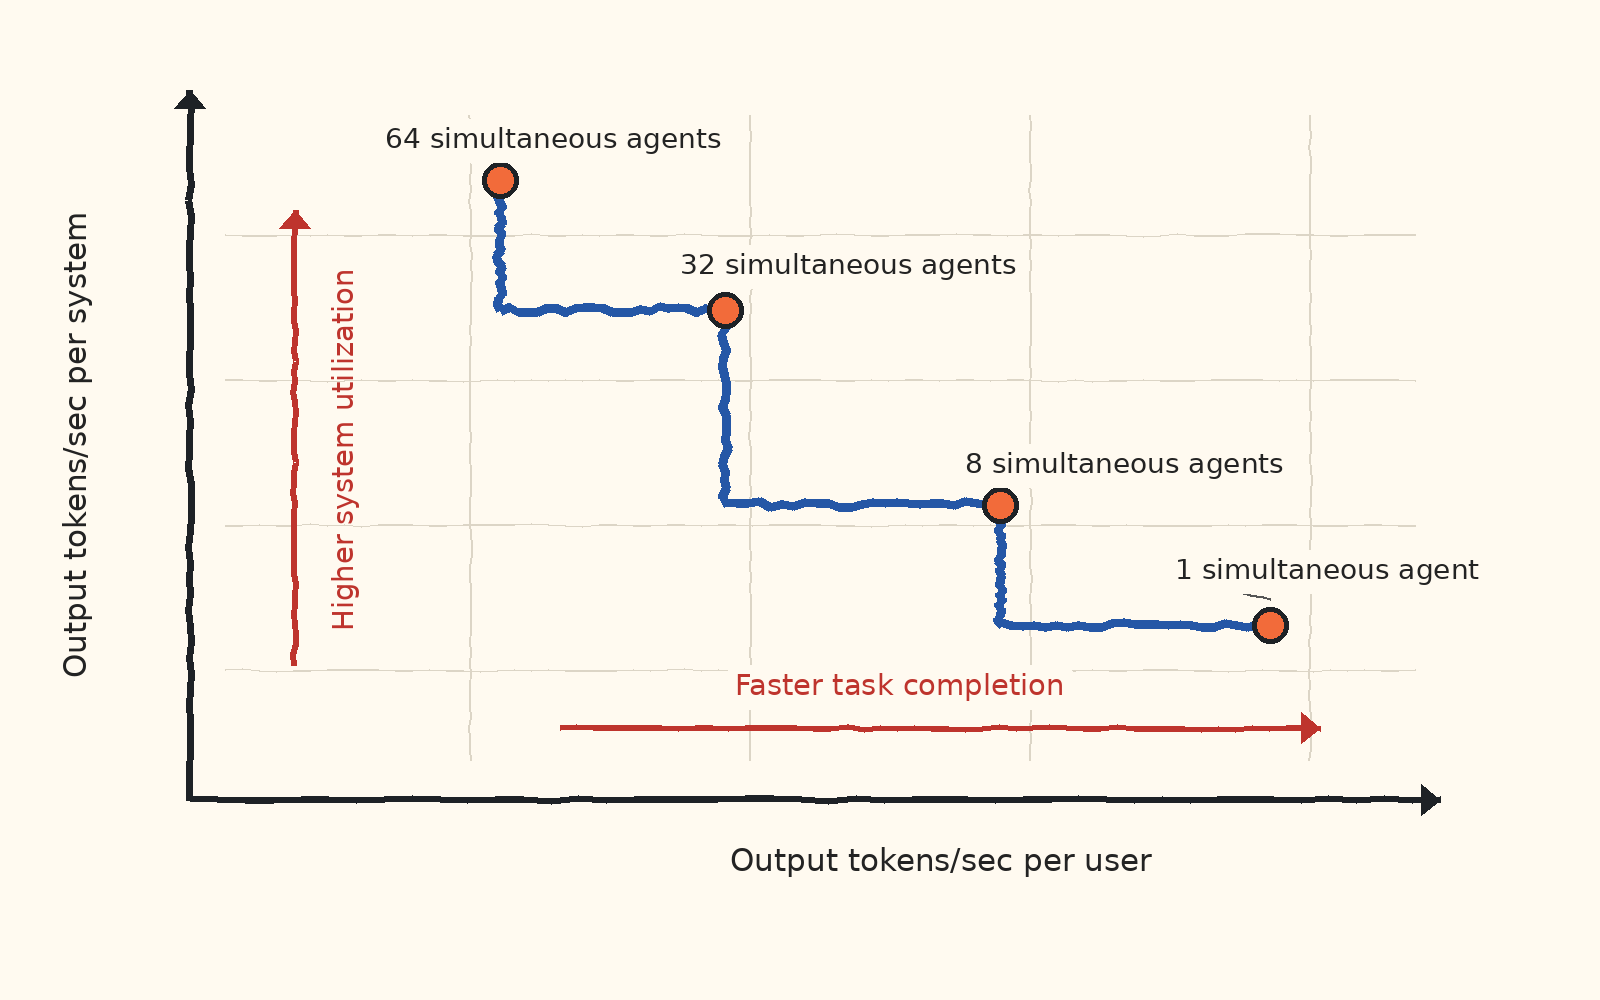
MLCommons launches MLPerf Endpoints v0.7, a foundation release with initial results from Coreweave, Google, Intel, KRAI, and NVIDIA. Rolling submissions and buyer-centric benchmarks coming with v1.0 later this year. || Focus Keyphrase | MLPerf Endpoints v0.7
Topics: Benchmarks
Entities: BenchmarksGoogleNVIDIACoreweave
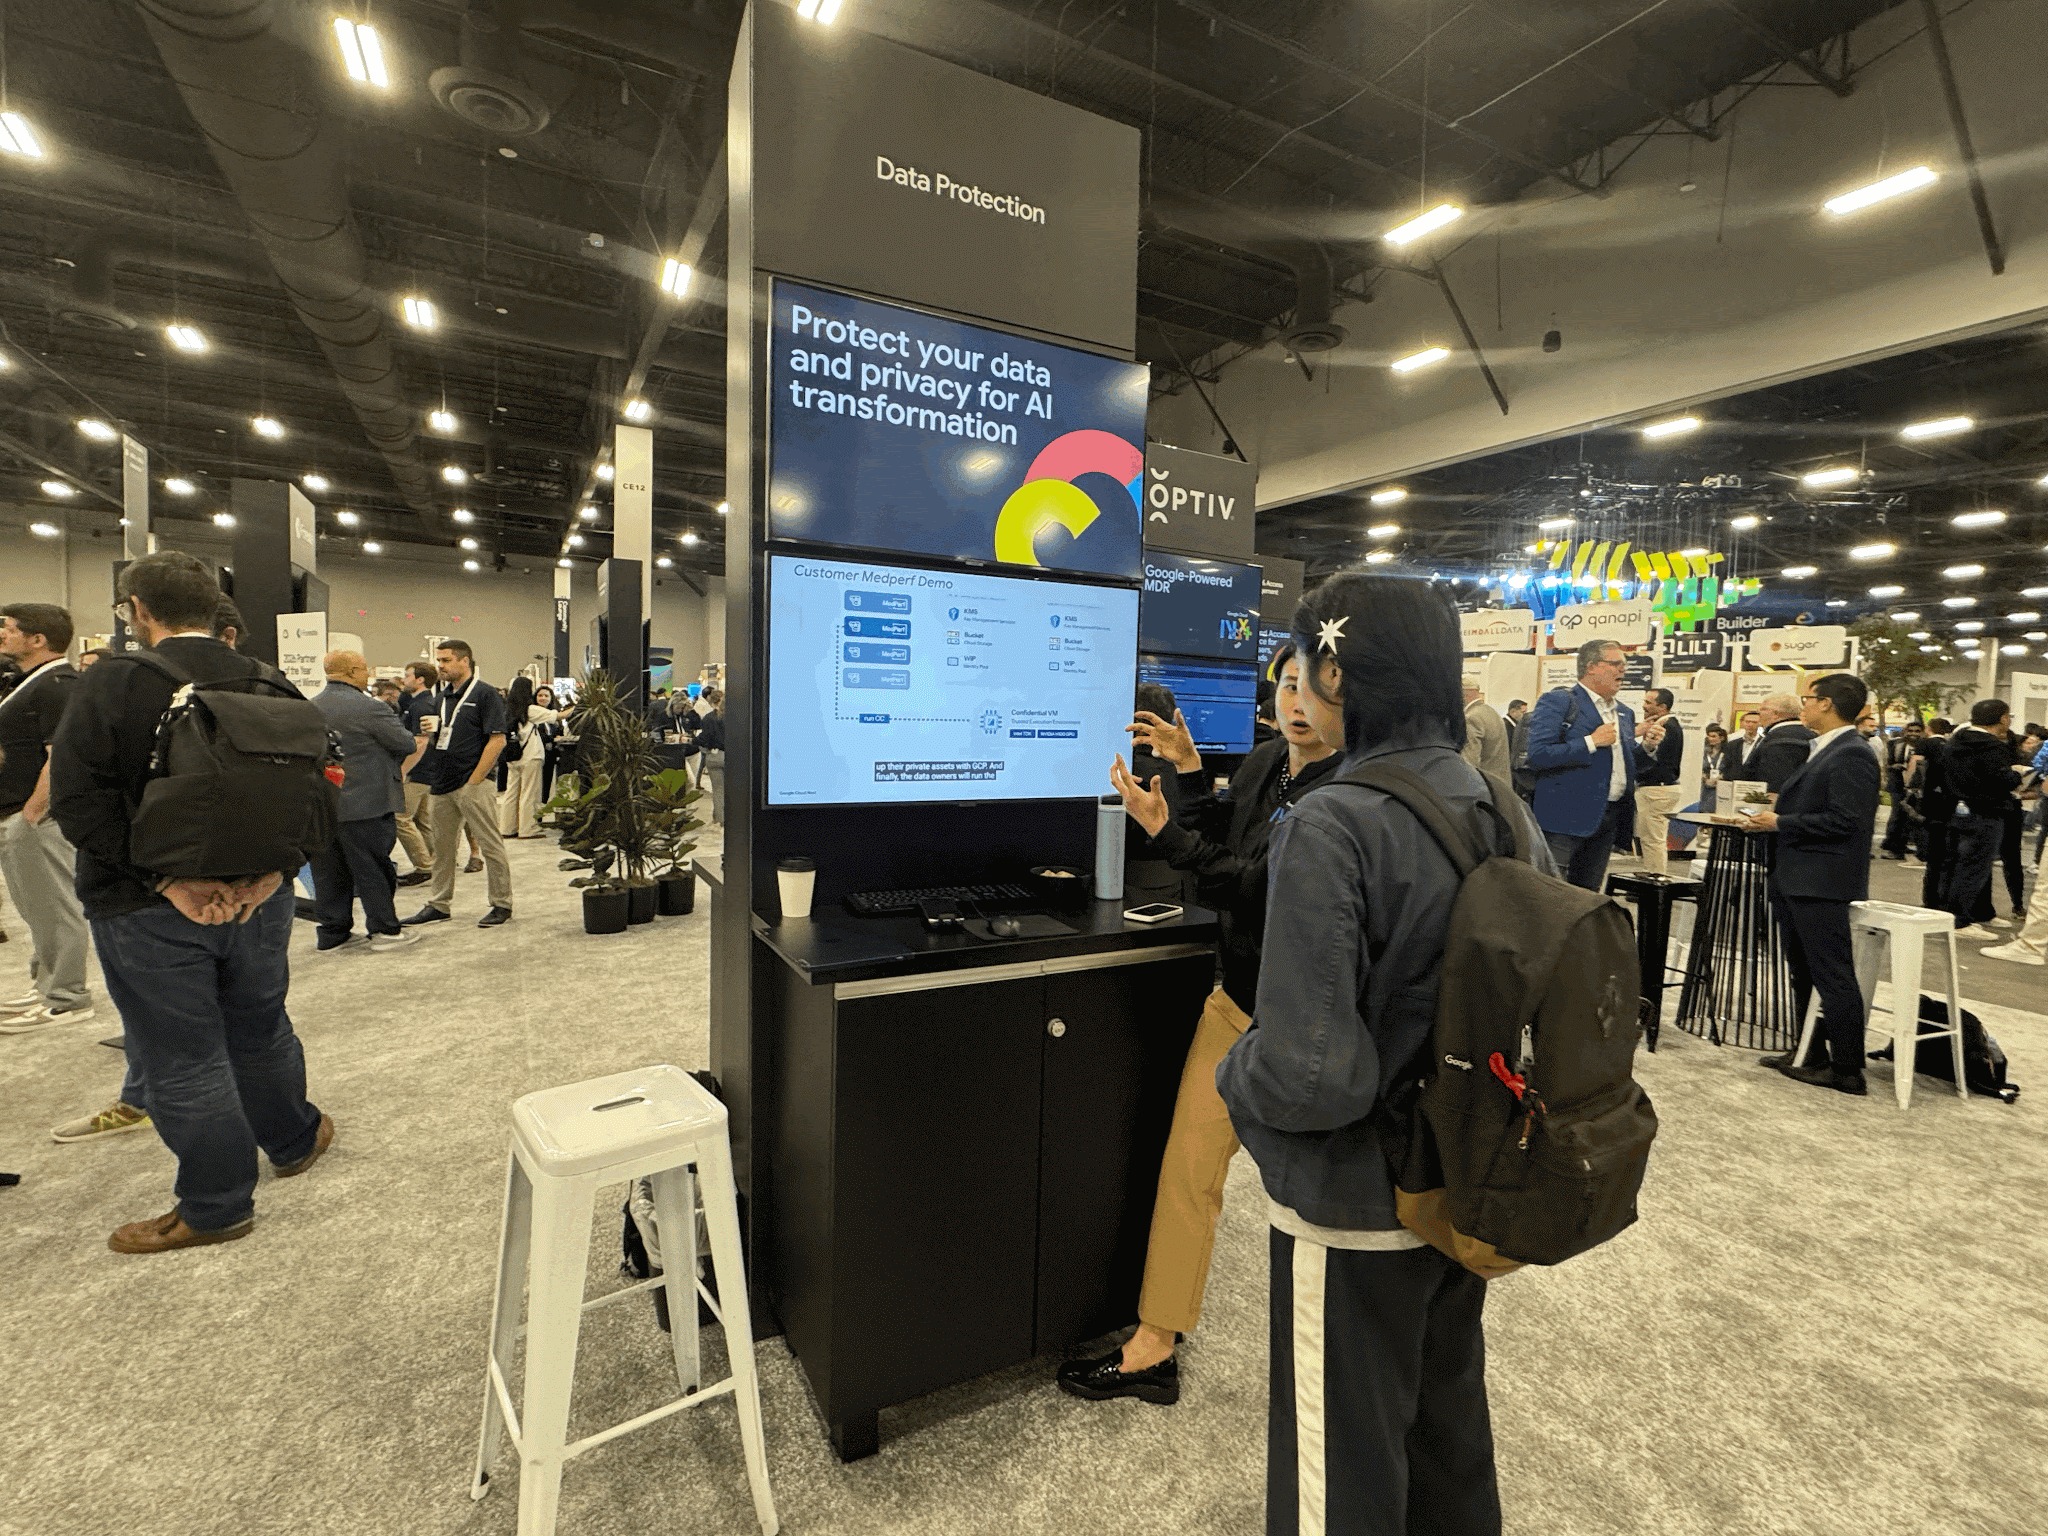
MLCommons and Google Cloud demonstrate MedPerf on Confidential Space - protecting patient data, model IP, and benchmark integrity for clinical AI research.
Topics: Benchmarks
Entities: BenchmarksGoogle
MLCommons introduces a new Edge Agentic Inference benchmark for MLPerf Inference v6.1, targeting multi-turn tool-calling LLMs on a single edge accelerator. Submit by July 31, 2026.
Topics: Benchmarks
Entities: Benchmarks
MLCommons introduces a new multi-turn benchmark for measuring LLM serving systems under growing context and closed-loop agent workflows. Featuring Kimi K2.6 and Qwen3.6-35B-A3B. **Category:** Benchmarks, LLM, Agentic AI, Inference
Topics: Benchmarks
Entities: Benchmarks
earn how MLPerf® Tiny benchmarks ultra-low-power AI systems using latency, accuracy, and energy metrics across five edge AI tasks.
Topics: Benchmarks
Entities: Benchmarks
MLCommons releases MLPerf Training v6.0 results: two new MoE benchmarks, 95 unique systems from 24 organizations across 13 hardware accelerators.
Topics: Benchmarks
Entities: Benchmarks
MLCommons introduces MLPerf Mobile v6.0, featuring new generative AI benchmarks to quantify on-device LLM inference using Llama 3.1 and 3.2. Read more.
Topics: Benchmarks
Entities: Benchmarks
Traditional coordinated vulnerability disclosure assumes systems can be patched. Here is why that breaks down for AI, and how MLCommons is building a new standard.