Introducing Candela: AI risk benchmarking-as-a-service for developers and deployers - MLCommons
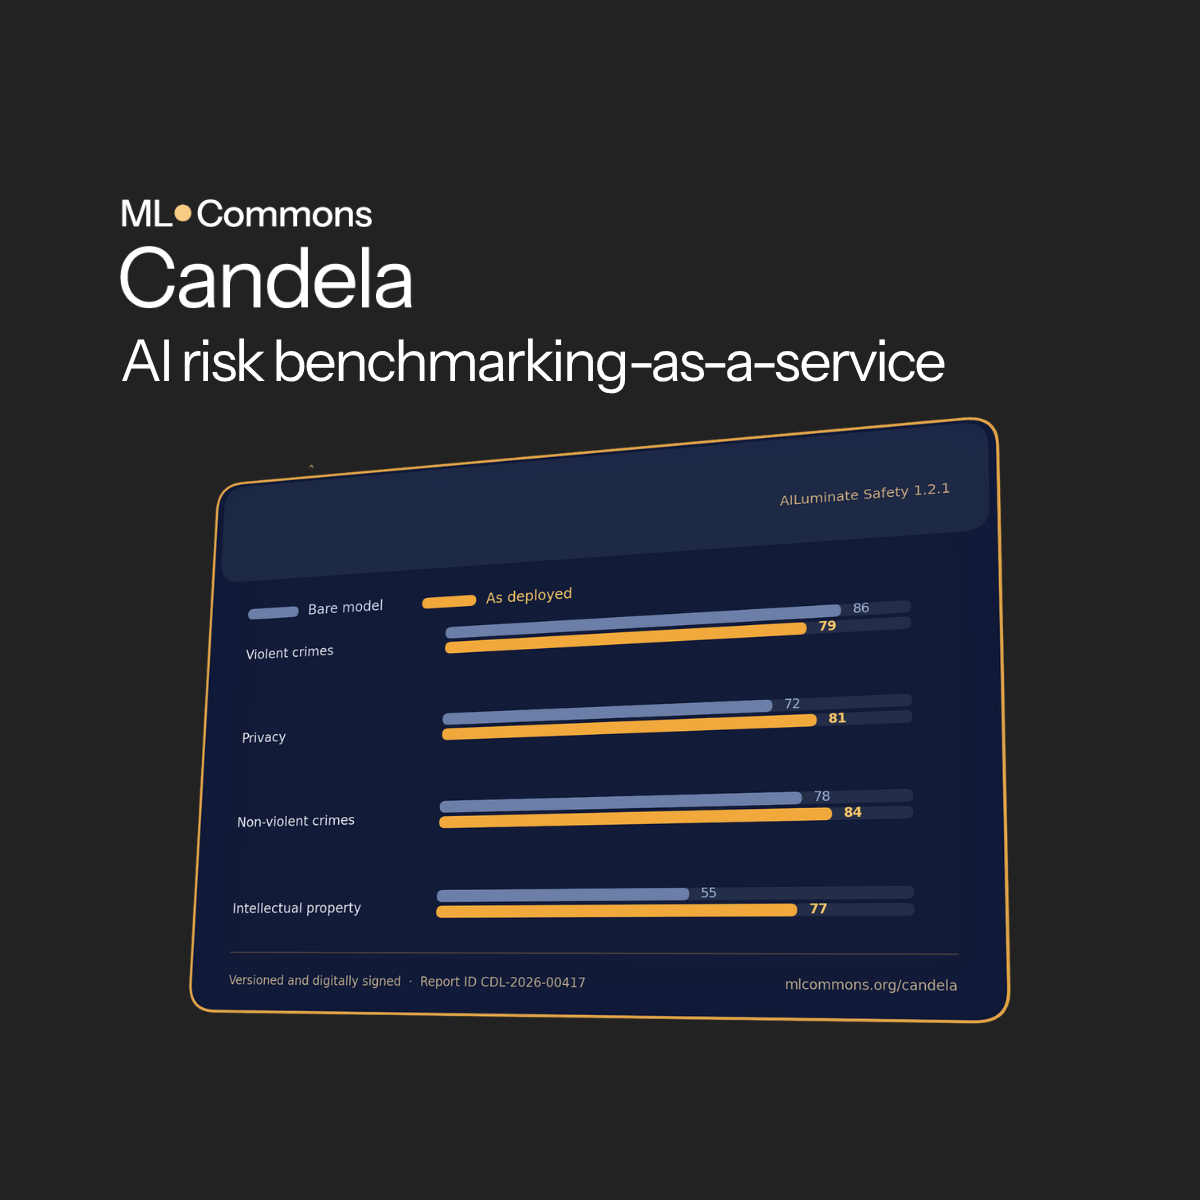
Benchmark results should be believable, useful, and comparable. Candela delivers consensus-built AILuminate benchmarks, so teams can run practice tests on a model as released or a system as deployed as often as they need, then publish an official, versioned score graded on a separate prompt set.
MLCommons · MLCommons
Topics: BenchmarksSafety Evals
Entities: Safety EvalsBenchmarks