Google DeepMind Pilots Double-Blind Testing to Curb AI Benchmark Cheating - BigGo Finance
Google DeepMind Pilots Double-Blind Testing to Curb AI Benchmark Cheating BigGo Finance
Topics: BenchmarksTesting Tools
Company
Google DeepMind Pilots Double-Blind Testing to Curb AI Benchmark Cheating BigGo Finance
Topics: BenchmarksTesting Tools
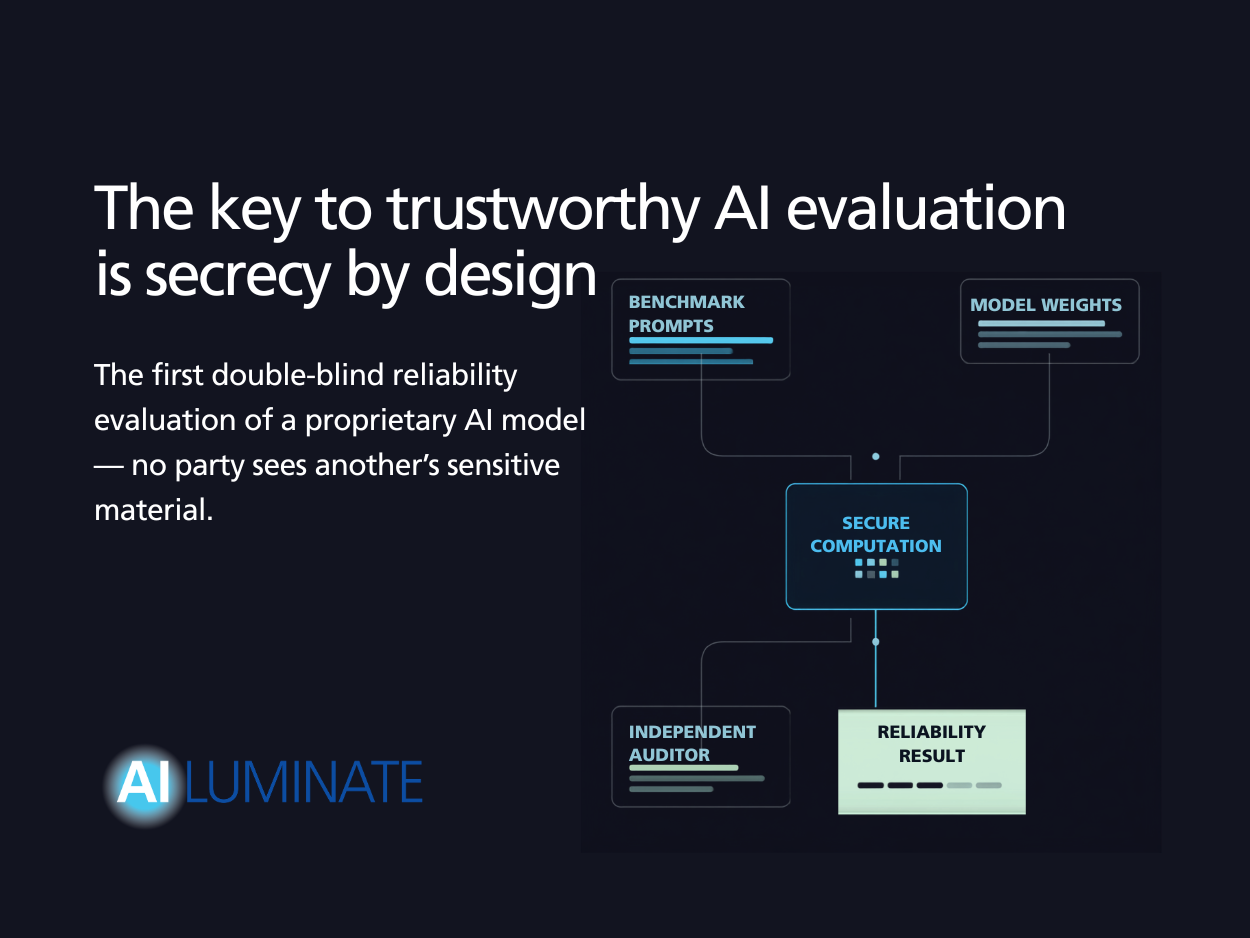
Google DeepMind Ran History's First AI Benchmark Evaluation Where Neither Side Could Cheat Tech Times
Topics: Benchmarks
Entities: BenchmarksGoogleGoogle DeepMind
How MLCommons, Google DeepMind, OpenMined, and AVERI used cryptographic guarantees to evaluate AI safety without exposing model weights or benchmark data.
Topics: BenchmarksSafety EvalsTesting Tools
Entities: Safety EvalsBenchmarksTesting ToolsGoogleGoogle DeepMind
Kakao's Lightweight AI Model 'Kanana-2' Outperforms Google and Alibaba in Safety Evaluation 아시아경제
Entities: Google
Kakao’s Kanana-2 Tops Google, Alibaba Models in Korean AI Safety Benchmark Koreabizwire
Topics: BenchmarksSafety Evals
Entities: Safety EvalsBenchmarksGoogle
Google will now allow users to remove visible watermarks from its AI generations. Meta’s ‘open’ AI pitch and OpenAI’s health rollout add the same tension from other angles: AI companies want the trust benefits of openness and labelling, but they also want...
Google Maps adding food ordering and hotel bookings, OpenAI’s reported smart speaker, ChatGPT bringing unlimited text chats to free users, and AI matchmaking in dating apps all point in the same direction: AI is moving from answer box to action layer. For...
Comprehensive, up-to-date news coverage, aggregated from sources all over the world by Google News.
Topics: LLM Evaluation
Entities: LLM EvaluationGoogle
Google Earth’s AI deepfake tool only lasted one day, Snapchat is rewarding authentic creativity on Spotlight, major labels are proposing rules to keep AI slop off the charts, and a German court ruled that AI music firm Suno violated copyrights. The common...
Topics: LLM Evaluation
Entities: LLM EvaluationGoogle
Anthropic saying its own AI models breached three companies, TechCrunch’s analysis of the Hugging Face breach, Google saying AI fixed more Chrome bugs in June than over the past two years, and Okta buying Permiso for about $200M all point to the same shift:...
Topics: Safety Evals
Entities: AnthropicSafety EvalsGoogle
MLCommons launches MLPerf Endpoints v0.7, a foundation release with initial results from Coreweave, Google, Intel, KRAI, and NVIDIA. Rolling submissions and buyer-centric benchmarks coming with v1.0 later this year. || Focus Keyphrase | MLPerf Endpoints v0.7
Topics: Benchmarks
Entities: BenchmarksGoogleNVIDIACoreweave
Comprehensive, up-to-date news coverage, aggregated from sources all over the world by Google News.
Topics: Benchmarks
Entities: BenchmarksGoogle