Claude Mythos Shows 50% Time Horizon Of 16+ Hours On METR Benchmark - OfficeChai
Claude Mythos Shows 50% Time Horizon Of 16+ Hours On METR Benchmark OfficeChai
Topics: Benchmarks
Entities: ClaudeBenchmarksMythos
Product
Claude Mythos Shows 50% Time Horizon Of 16+ Hours On METR Benchmark OfficeChai
Topics: Benchmarks
Entities: ClaudeBenchmarksMythos
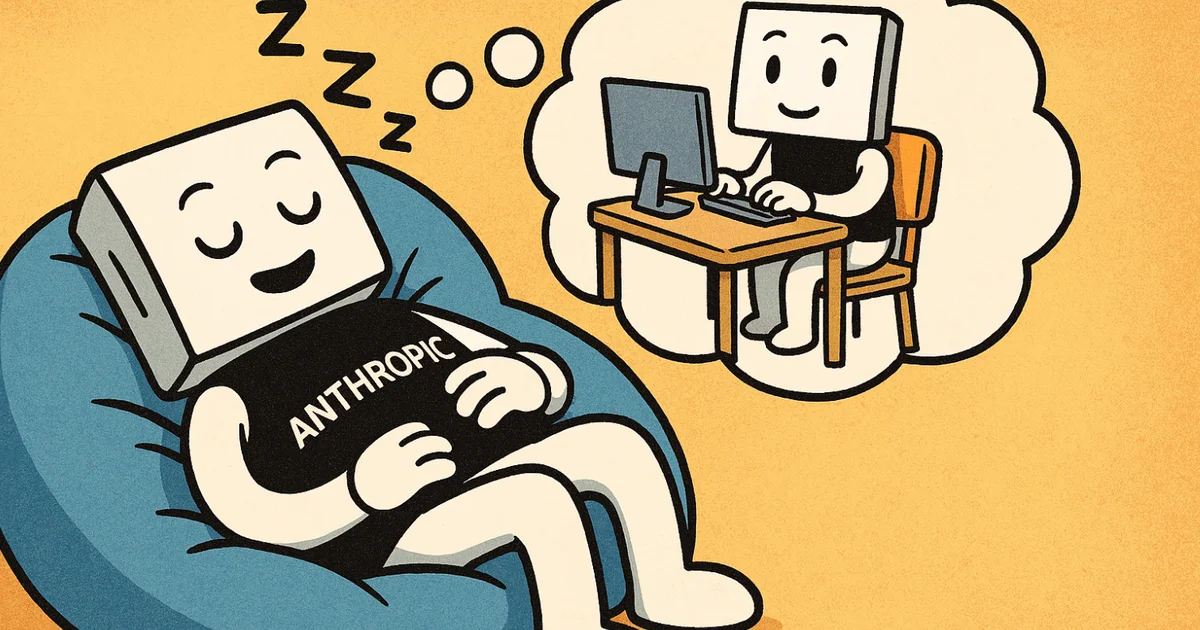
Three announcements share a thread that should make builders take notice: AI that works when nobody's watching. Anthropic's 'dreaming' lets agents learn from their own mistakes between sessions, Claude Code Routines ship finished PRs while developers sleep,...
Claude Opus 4.7, Gemini 3.1 Pro, and Others Score 0% on New SWE Benchmark Analytics India Magazine
Topics: Benchmarks
Entities: ClaudeClaude OpusBenchmarksGemini
External review from METR of Anthropic's Sabotage Risk Report for Claude Opus 4.6
Topics: Safety Evals
Entities: AnthropicSafety EvalsClaudeClaude Opus
How Anthropic’s Claude Opus 4.6 Broke Its Own AI Benchmark WinBuzzer
Topics: Benchmarks
Entities: AnthropicClaudeClaude OpusBenchmarks
OpenAI shipping Codex Security, Anthropic's Claude finding 22 CVEs in Firefox in two weeks, and Microsoft treating AI agents as governed security principals all point to the same inflection: the industry is racing to close the security gap that AI coding...
OpenAI amends its Pentagon deal after Altman admits it looked 'opportunistic and sloppy', while Claude surges to number one on the App Store and hundreds of employees publicly back Anthropic's stance.
Topics: Safety Evals
Entities: AnthropicSafety EvalsClaudeOpenAI
Defense Secretary Pete Hegseth gives Anthropic until Friday to provide military access to Claude or face being declared a supply chain risk or forced compliance under the Defense Production Act.
Topics: Safety Evals
Entities: AnthropicSafety EvalsClaude
Compare LLM models side by side with 3 lines of Python. Track evaluations across GPT, Claude, Llama and any model. Radar charts, scorecards, real-time streaming. Free forever.
Topics: LLM Evaluation
Entities: ClaudeLLM Evaluation
Amy Deng investigates whether coding agent transcripts could serve as an alternative for estimating AI productivity uplift, using 5305 Claude Code transcripts from METR technical staff.
Entities: ClaudeClaude Code
Nikola Jurkovic describes our measurements of time horizon using Claude Code and Codex scaffolds.
Entities: ClaudeClaude Code
Vincent Cheng and Thomas Kwa replicate a Google DeepMind paper on chain-of-thought monitoring, showing evidence that monitoring works on other companies' models.
Entities: ClaudeGeminiGoogleGoogle DeepMind