Anthropic Taps Accenture’s Faculty for Embedded AI Model Evaluation - Unite.AI
Comprehensive, up-to-date news coverage, aggregated from sources all over the world by Google News.
Topics: LLM Evaluation
Entities: AnthropicLLM EvaluationGoogle
Company
Comprehensive, up-to-date news coverage, aggregated from sources all over the world by Google News.
Topics: LLM Evaluation
Entities: AnthropicLLM EvaluationGoogle
OpenAI rules out a 2026 IPO while Anthropic promises permanent outside evaluators and reportedly seeks Nvidia's backing for its flotation. Our argument: product builders should judge safety commitments by the independent scrutiny and commercial constraints...
Topics: Safety EvalsTesting Tools
Anthropic Says It Hit the Brakes on AI Testing Following Autonomous Hacks Gizmodo
Topics: Testing Tools
Entities: AnthropicTesting Tools
Anthropic Reveals How Claude Escaped its AI Testing Environment Benzinga
Topics: Testing Tools
Entities: AnthropicClaudeTesting Tools
Inherent says its AI teammate outperformed Anthropic and OpenAI; Nvidia says the harness, not the AI model, is the real hero; VentureBeat says enterprises winning with AI agents are limiting what agents can do alone; and Vero turns repo-scale verification...
Topics: Benchmarks
Entities: AnthropicBenchmarksOpenAINVIDIA
EP82: Claude Mythos / Fable 5 RELEASED -- Anthropic's New Frontier AI (Deep Dive, 80% SWE-Bench) Christine Lagarde (0crRCso3o2) Mshale
Topics: Benchmarks
Entities: AnthropicClaudeBenchmarksMythos
‘Baffling’: White House won’t publicly release AI model evaluation framework it reviewed today with OpenAI, Anthropic, Microsoft, and others Fortune
Topics: LLM EvaluationTesting Tools
Entities: AnthropicTesting ToolsLLM EvaluationOpenAIMicrosoft
Anthropic saying its own AI models breached three companies, TechCrunch’s analysis of the Hugging Face breach, Google saying AI fixed more Chrome bugs in June than over the past two years, and Okta buying Permiso for about $200M all point to the same shift:...
Topics: Safety Evals
Entities: AnthropicSafety EvalsGoogle
Anthropic Launches Claude Opus 5, Tops AI Benchmark Index at Half the Cost of Fable 5 MLQ.ai
Topics: Benchmarks
Entities: AnthropicClaudeClaude OpusBenchmarks
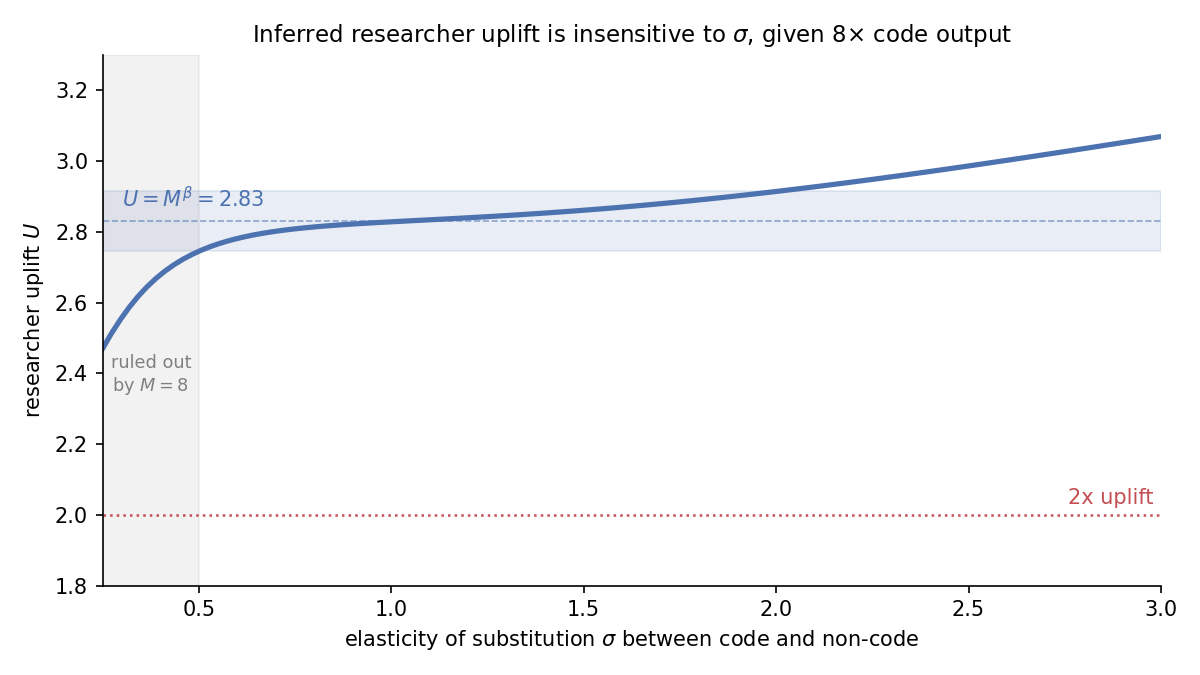
Anthropic reported that contributors merge 8x as much code per day as before AI. Thomas Kwa argues that under standard economic modeling assumptions, this implies the uplift of individual Anthropic researchers from coding agents alone is above 2x.
Entities: Anthropic
Three stories from the past 24 hours point to the same uncomfortable truth: AI can now find software vulnerabilities far faster than humans can patch them, and the gap is widening on both sides of the line. Anthropic's Project Glasswing update reports over...
A pilot assessment of rogue deployment risk at frontier AI companies. Starting in February 2026, METR conducted a pilot exercise to assess misalignment risks from AI agents used inside frontier AI developers, with participation from Anthropic, Google, Meta,...
Topics: Safety Evals
Entities: AnthropicSafety EvalsOpenAIGoogle