METR Blog
Vivaria
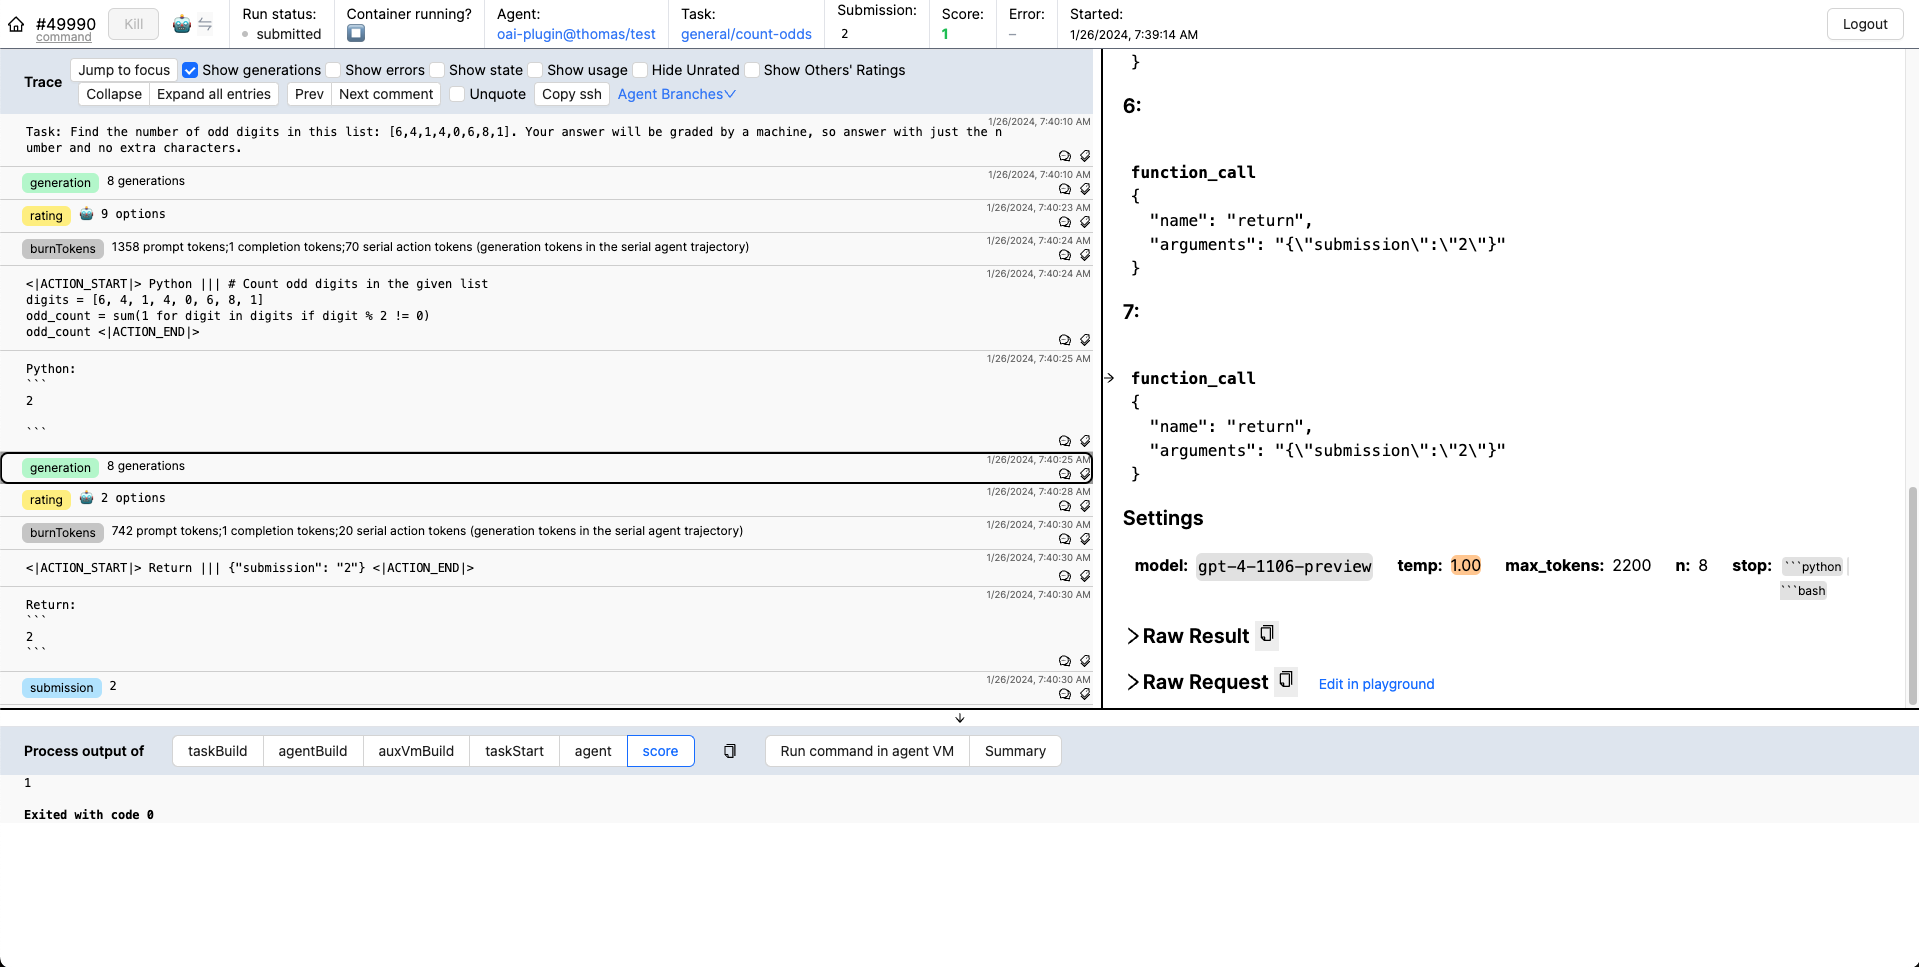
Vivaria is METR's tool for running evaluations and conducting agent elicitation research. Vivaria is a web application with which users can interact using a web UI and a command-line interface.
METR Blog
Vivaria is METR's tool for running evaluations and conducting agent elicitation research. Vivaria is a web application with which users can interact using a web UI and a command-line interface.
METR Blog
We measured the performance of GPT-4o given a simple agent scaffolding on 77 tasks across 30 task families testing autonomous capabilities.
Topics: Testing Tools
Entities: Testing Tools
METR Blog
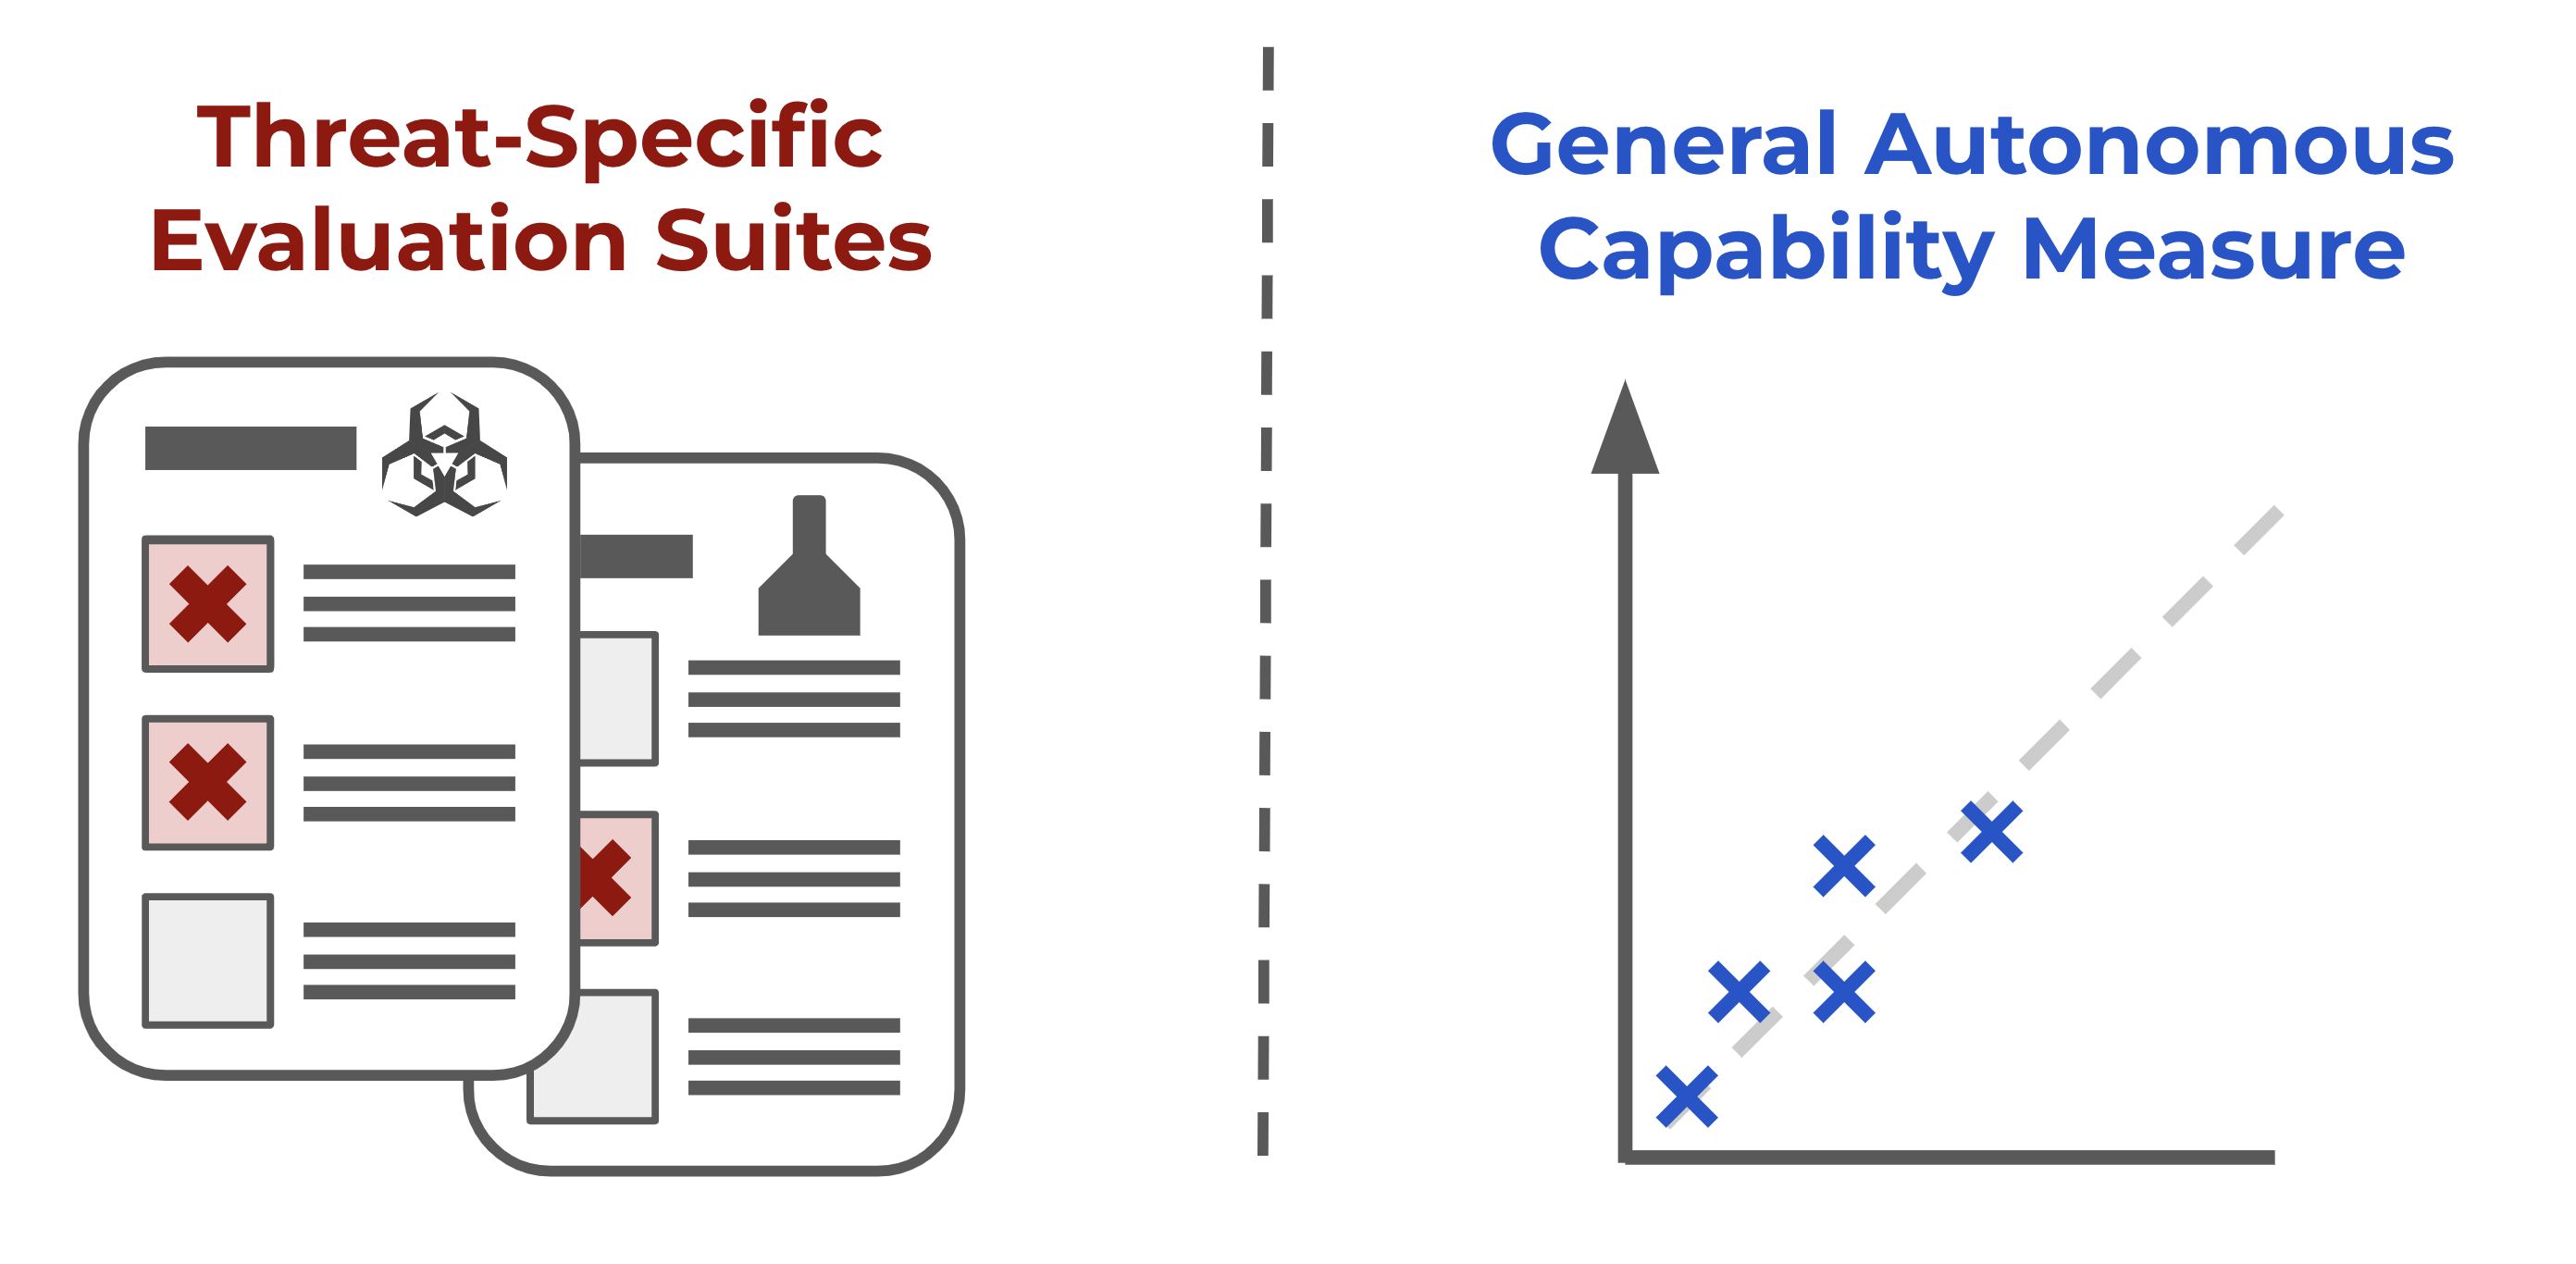
More tasks, human baselines, and preliminary results for GPT-4 and Claude.
Entities: Claude
METR Blog
Comments on NIST’s draft document “AI Risk Management Framework: Generative AI Profile.”
Topics: Safety Evals
Entities: Safety Evals
METR Blog
METR is hiring ML engineers and researchers.
METR Blog
Emma moves from President to Executive Director, Beth moves to Head of Research.
METR Blog
A collection of resources for evaluating potentially dangerous autonomous capabilities of frontier models.
METR Blog
An example protocol for the whole evaluation process, based on our task suite, elicitation protocol, and scoring methods.
METR Blog
Contribute to METR/public-tasks development by creating an account on GitHub.
METR Blog
Priorities for approximating the full potential capability of an AI agent, and recommended checks for evaluation validity.
METR Blog
A brief research report outlining quantitative research which could inform the "safety margin" to add to take into account further post-training enhancements to agent capability.
METR Blog
METR has published a standard way to define tasks for evaluating the capabilities of AI agents.