OpenAI Evaluation Filter

Frontier risk and preparedness

To support the safety of highly-capable AI systems, we are developing our approach to catastrophic risk preparedness, including building a Preparedness team and launching a challenge.

Topics: Safety Evals

Entities: Safety Evals
METR Blog

Políticas de escalamiento responsable (RSP)

Describimos los componentes básicos de las políticas de escalamiento responsable (RSP) y por qué creemos que pueden ayudar a reducir los riesgos catastróficos de la IA.

METR Blog

负责任扩展政策(RSP)

本文介绍负责任扩展政策(RSP)的基本内容,以及为什么我们认为 RSP 有望降低 AI 带来的灾难性风险。

METR Blog

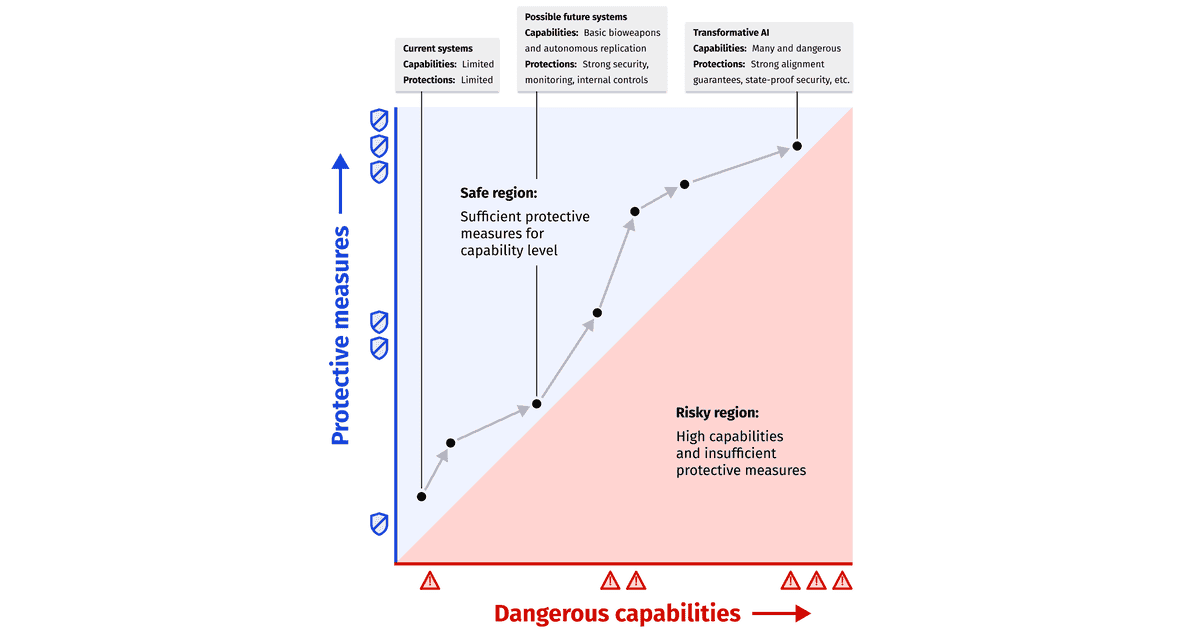
Responsible Scaling Policies (RSPs)

We describe the basic components of Responsible Scaling Policies (RSPs) as well as why we find them promising for reducing catastrophic risks from AI.

METR Blog

ARC Evals is spinning out from ARC

ARC Evals plans to spin out from the Alignment Research Center (ARC) in the coming months, and become its own standalone organization.

OpenAI Evaluation Filter

GPT-4

We’ve created GPT-4, the latest milestone in OpenAI’s effort in scaling up deep learning. GPT-4 is a large multimodal model (accepting image and text inputs, emitting text outputs) that, while less capable than humans in many real-world scenarios, exhibits...

Topics: Benchmarks

Entities: BenchmarksOpenAI

More stories

More stories load automatically as you scroll.