OpenAI o3-mini System Card
This report outlines the safety work carried out for the OpenAI o3-mini model, including safety evaluations, external red teaming, and Preparedness Framework evaluations.
Topics: Safety Evals
Entities: Safety EvalsOpenAI
Community feed
A focused stream of recent stories from the sources curated for this community. Latest: OpenAI o3-mini System Card, An update on our preliminary evaluations of Claude 3.5 Sonnet and o1, and Track LLM model evaluation using Amazon SageMaker managed MLflow and FMEval | Amazon Web Services - Amazon Web Services (AWS). Page 66.
This report outlines the safety work carried out for the OpenAI o3-mini model, including safety evaluations, external red teaming, and Preparedness Framework evaluations.
Topics: Safety Evals
Entities: Safety EvalsOpenAI
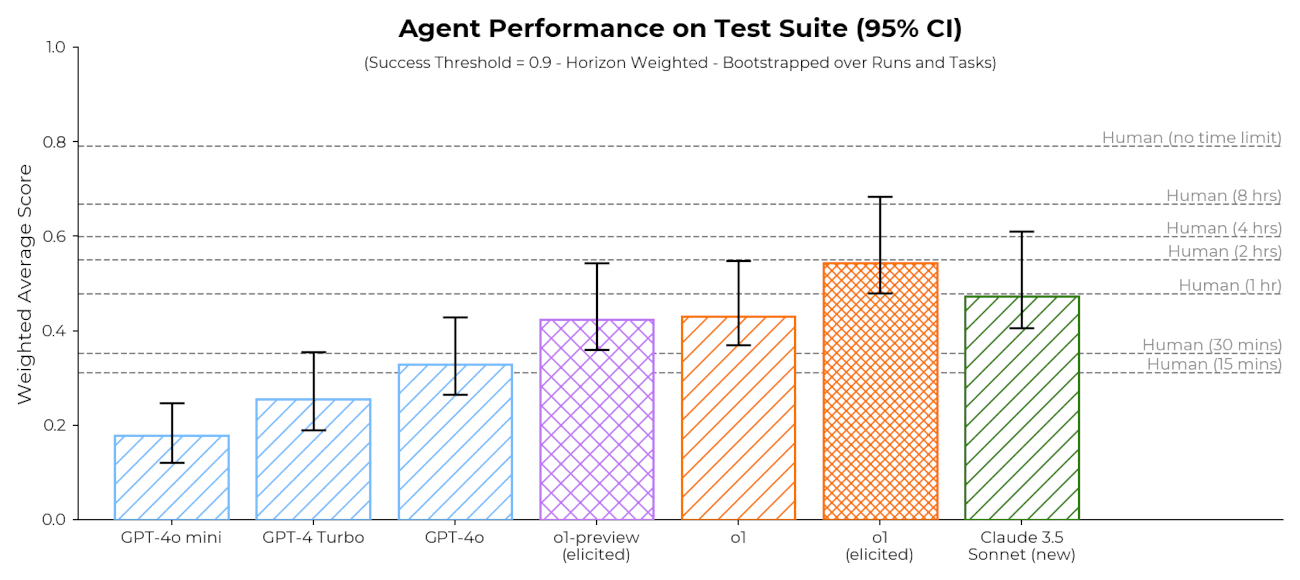
Preliminary evaluations of Claude 3.5 Sonnet (New) and o1, as well as some discussion of challenges in making capability-based safety arguments for AI models.
Entities: Claude
Track LLM model evaluation using Amazon SageMaker managed MLflow and FMEval | Amazon Web Services Amazon Web Services (AWS)
Topics: LLM Evaluation
Drawing from OpenAI’s established safety frameworks, this document highlights our multi-layered approach, including model and product mitigations we’ve implemented to protect against prompt engineering and jailbreaks, protect privacy and security, as well...
Entities: OpenAI
Why pre-deployment testing is not an adequate framework for AI risk management
Topics: Safety EvalsTesting Tools
Entities: Safety EvalsTesting Tools
We’re on a journey to advance and democratize artificial intelligence through open source and open science.
Topics: Benchmarks
Entities: Benchmarks
What Makes a Good AI Benchmark? Stanford HAI
Topics: Benchmarks
Entities: Benchmarks
This report outlines the safety work carried out prior to releasing OpenAI o1 and o1-mini, including external red teaming and frontier risk evaluations according to our Preparedness Framework.
Topics: Safety Evals
Entities: Safety EvalsOpenAI
We’re on a journey to advance and democratize artificial intelligence through open source and open science.
Topics: BenchmarksLLM Evaluation
Entities: BenchmarksLLM Evaluation
We’re releasing RE-Bench, a new benchmark for measuring the performance of humans and frontier model agents on ML research engineering tasks. We also share data from 71 human expert attempts and results for Anthropic’s Claude 3.5 Sonnet and OpenAI’s...
Topics: Benchmarks
Entities: AnthropicClaudeBenchmarksOpenAI
We’re on a journey to advance and democratize artificial intelligence through open source and open science.
Topics: Benchmarks
Entities: Benchmarks
Thoughts on how AI agents might develop large and resilient rogue populations.