MLPerf Training v6.1 Results: Record Participation
MLPerf Training v6.1 results are out: 24 submitting organizations, two new benchmarks, and first NVIDIA Rubin and Google TPUv7 results.
Topics: Benchmarks
Entities: BenchmarksGoogleNVIDIA
Source feed
36 items
MLCommons aims to accelerate AI innovation to benefit everyone. It's philosophy of open collaboration and collaborative engineering seeks to improve AI systems by continually measuring and improving the accuracy, safety, speed and efficiency of AI technologies. We help companies and universities around the world build better AI systems that will benefit society.
MLPerf Training v6.1 results are out: 24 submitting organizations, two new benchmarks, and first NVIDIA Rubin and Google TPUv7 results.
Topics: Benchmarks
Entities: BenchmarksGoogleNVIDIA
Benchmark results should be believable, useful, and comparable. Candela delivers consensus-built AILuminate benchmarks, so teams can run practice tests on a model as released or a system as deployed as often as they need, then publish an official, versioned...
Topics: BenchmarksSafety Evals
Entities: Safety EvalsBenchmarks
Public results for 27 systems, a deterministic evaluator, and on-demand testing in Candela: AILuminate Safety 1.2.1 and Jailbreak 1.1 are here.
Topics: Testing Tools
Entities: Testing Tools
Teams deploy whole systems but cite safety scores from base models. Fine-tunes drift safety in unpredictable directions, and many benchmarks are too noisy to detect the change. This post explains why safety scoring is not composable, and what MLCommons is...
Topics: BenchmarksSafety Evals
Entities: Safety EvalsBenchmarks
MLCommons will develop MLPerf Agents, a benchmark for the efficiency of complete agentic AI workflows, through a $3.5 million NSF-backed AI Efficiency Challenge award from STRIDE Ventures.
Topics: Benchmarks
Entities: Benchmarks
MLPerf Endpoints measures the served endpoint the way you buy it: the full Pareto frontier across concurrency, five metrics, and results peer-reviewed by MLCommons.
Topics: Benchmarks
Entities: Benchmarks
MLPerf is the yardstick for the EU's AI Gigafactories tender, and MLPerf Endpoints v1.0 is open for submissions - rolling results, mandatory power reporting.
Topics: Benchmarks
Entities: Benchmarks
AI risk is already on your books. A business owner's guide to measuring, pricing, and managing it with independent benchmarks like AILuminate
Topics: BenchmarksSafety Evals
Entities: Safety EvalsBenchmarks
MLCommons' Privacy Working Group releases v0.1 of the Agent Privacy Risk Taxonomy: five areas of data protection risk unique to AI agents, from data ingestion to accountability and governance.
Topics: Safety Evals
Entities: Safety Evals
MLPerf Training introduces DLRMv4, a next-generation recommendation benchmark built on HSTU sequence modeling and the Yambda-5B dataset with a 560 GB production-class embedding footprint.- Focus keyphrase: DLRMv4 MLPerf Training
Topics: Benchmarks
Entities: Benchmarks
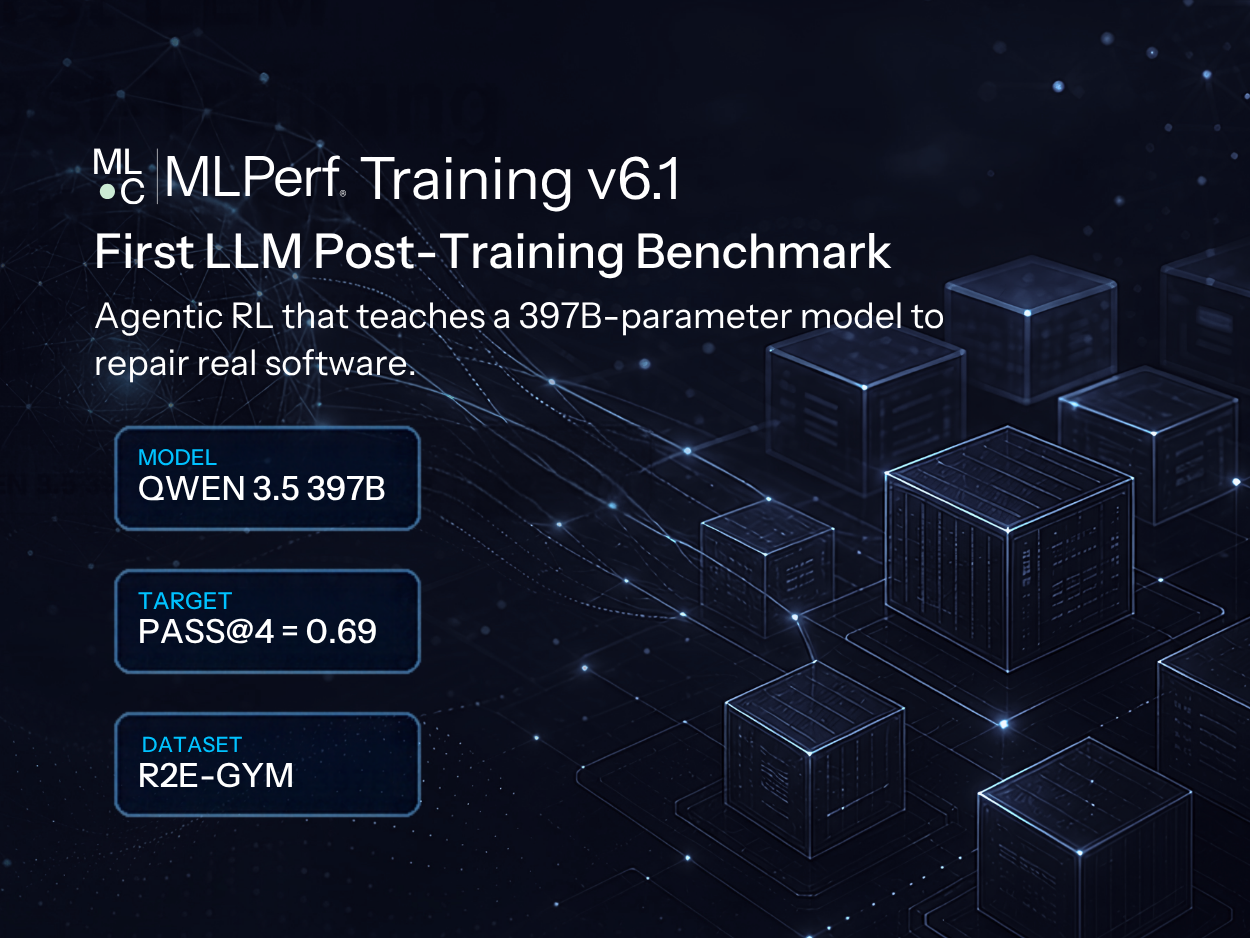
MLPerf Training v6.1 adds an agentic RL benchmark: teach a 397B-parameter model to repair real software. Reference run: 256 Blackwell Ultra GPUs.
Topics: Benchmarks
Entities: Benchmarks
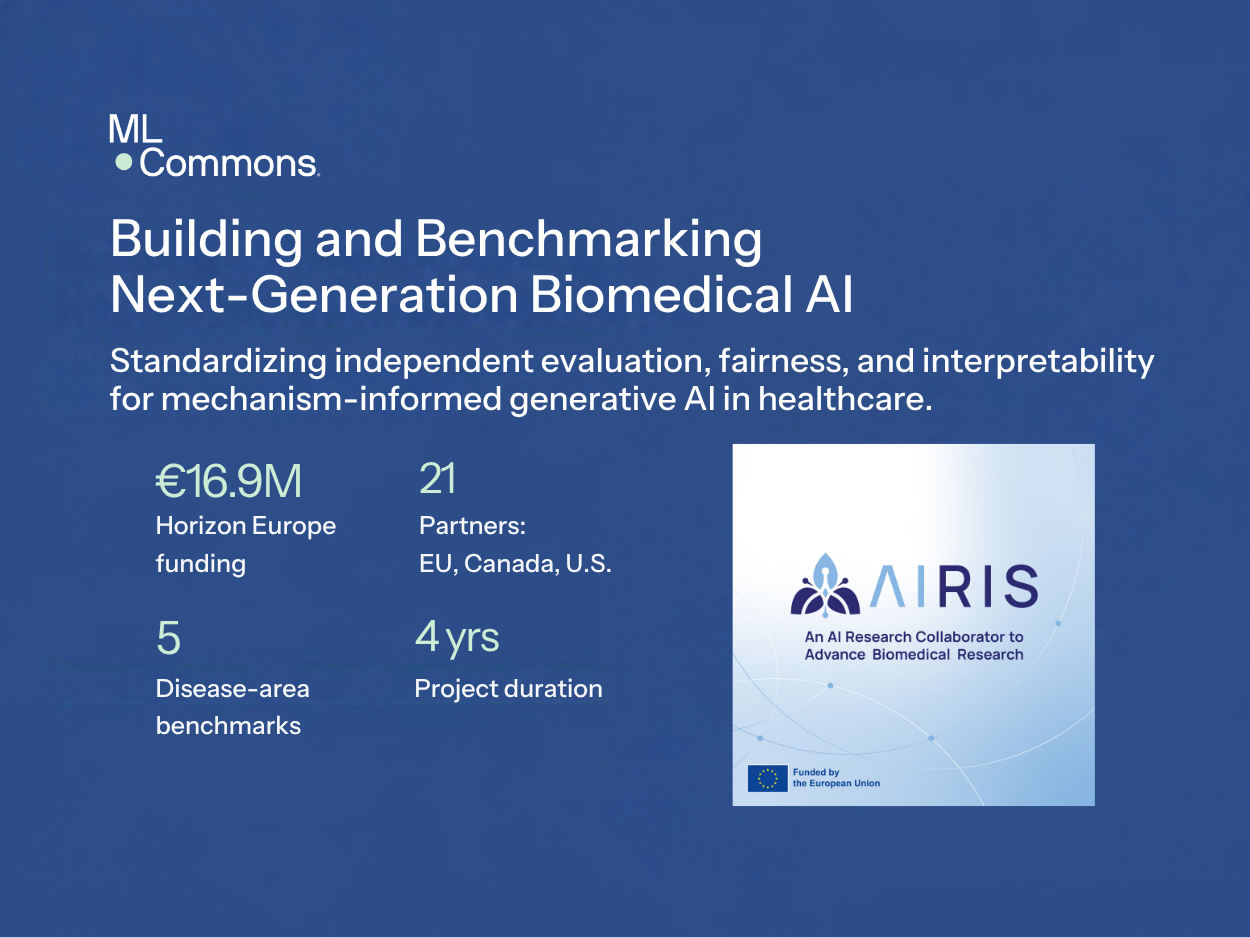
MLCommons joins the EU-funded AIRIS consortium to develop open benchmarks for mechanism-informed generative AI in biomedical research.
Topics: Benchmarks
Entities: Benchmarks