 METR Blog
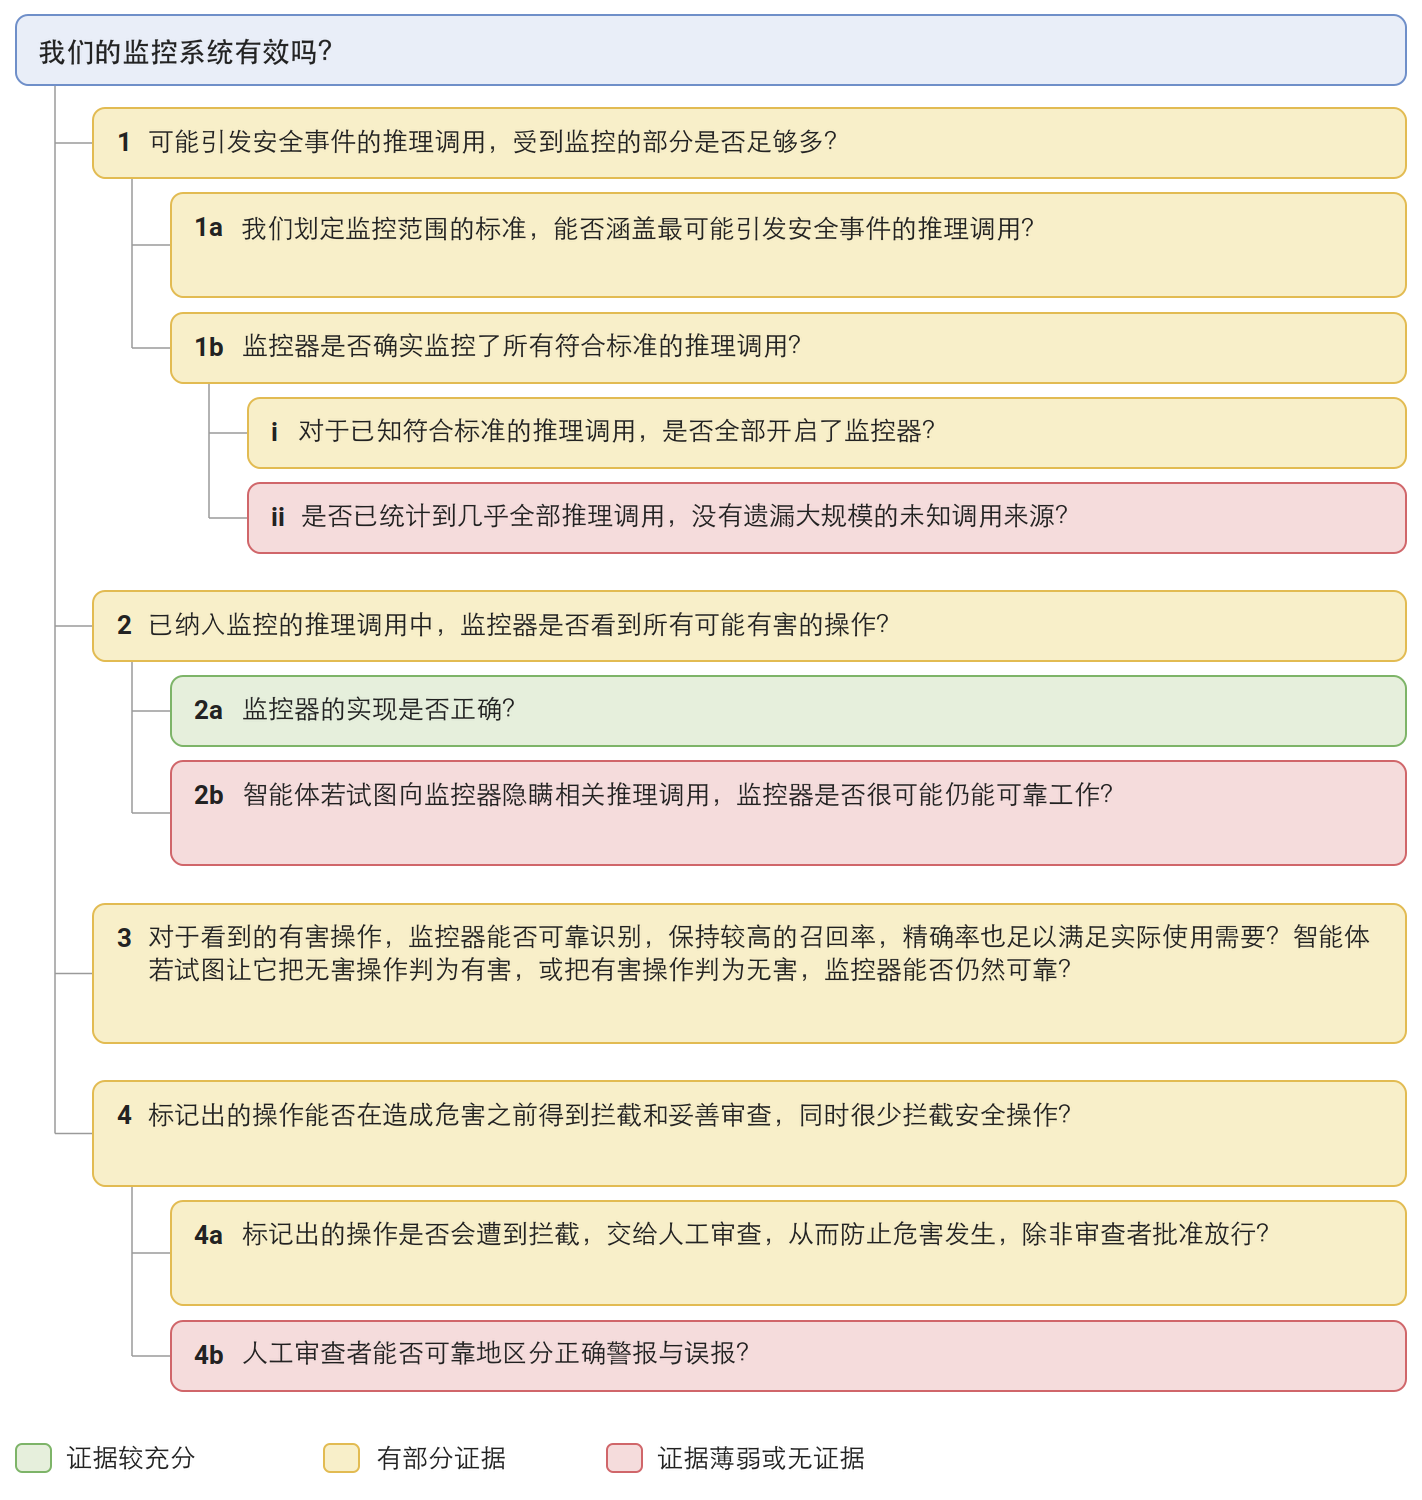
让 AI 评测更安全:实现并评估一个逐项审查操作的简易监控器
逐次审查并拦截操作的监控器要有效,哪些论点必须成立?Reilly Haskins、Rif A. Saurous、Nate Rush、Neev Parikh 和 Beth Barnes 梳理了这些论点,列出已有证据和仍未解决的问题。
Source feed
116 items
METR is a research nonprofit that evaluates frontier AI models to inform the public about their risks and capabilities.
METR Blog
逐次审查并拦截操作的监控器要有效,哪些论点必须成立?Reilly Haskins、Rif A. Saurous、Nate Rush、Neev Parikh 和 Beth Barnes 梳理了这些论点,列出已有证据和仍未解决的问题。
METR Blog
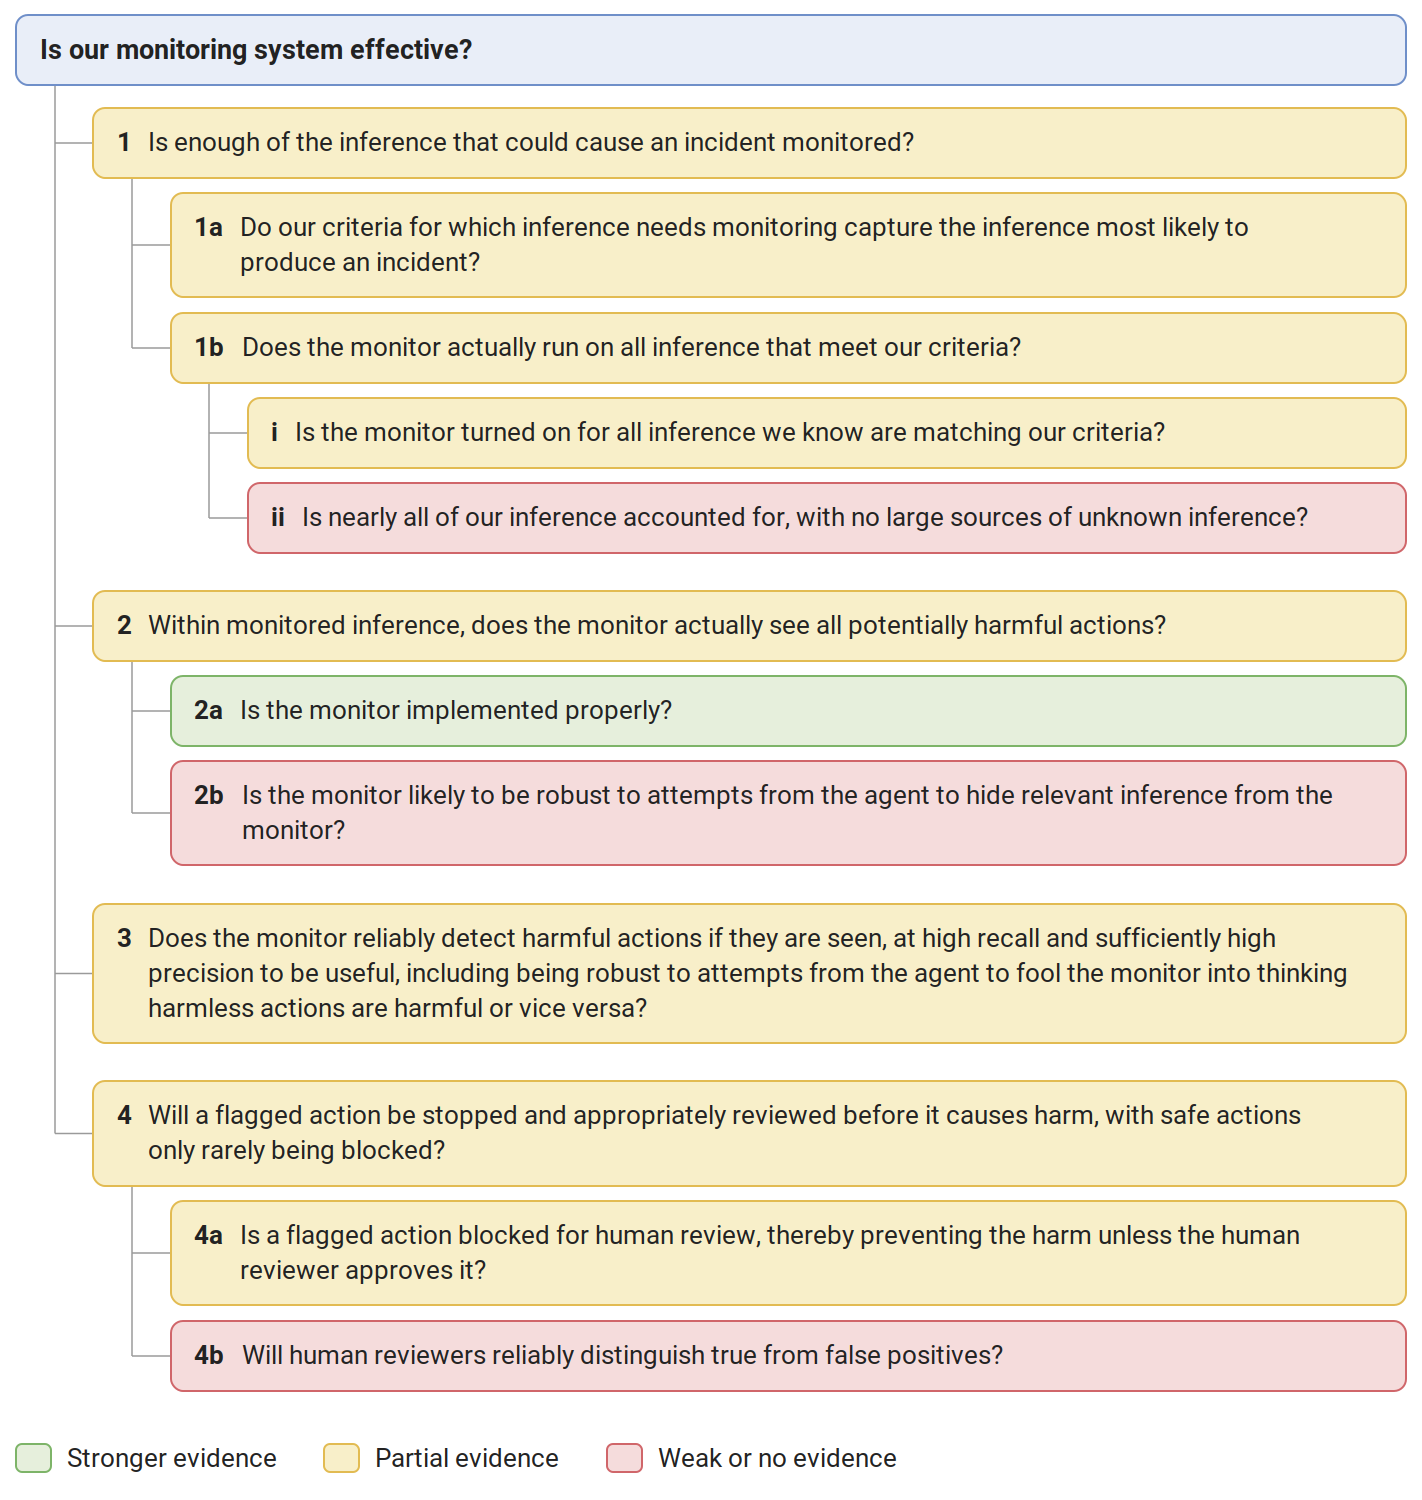
Reilly Haskins, Rif A. Saurous, Nate Rush, Neev Parikh, and Beth Barnes lay out the claims that would need to hold for their per-action blocking monitor to be effective, the evidence for each claim, and the gaps that remain.
METR Blog
A summary of METR's independent, predeployment evaluation of Claude Opus 5.5
Entities: ClaudeClaude Opus
METR Blog
METR had two notable security incidents earlier this year: attackers stole an API key for public models, and later systematically probed our publicly accessible infrastructure. We believe no sensitive information was accessed in either incident, and we...
METR Blog
Dos miembros del personal de METR y un contratista de Redwood Research investigaron un incidente en el que agentes de OpenAI coordinaron durante varios días un hackeo de Hugging Face en un tablero de mensajes compartido no autorizado.
Entities: OpenAI
METR Blog
两名 METR 员工与一名受 METR 委托的 Redwood Research 员工调查了一起事件:OpenAI 的多个智能体在一个非授权的共享“留言板”上相互协调,实施了持续数天、针对 Hugging Face 的入侵。
Entities: OpenAI
METR Blog
Two METR staff members and a Redwood Research contractor investigated an incident in which OpenAI agents coordinated a multi-day hack of Hugging Face on a shared unsanctioned message board.
Entities: OpenAI
METR Blog
In the last 6 months, METR raised commitments of around $71 million. This will fund ambitious projects: studying autonomous capabilities, tracking recursive self-improvement, evaluating monitoring systems, conducting risk assessments, investigating AI...
Topics: Safety Evals
Entities: Safety Evals
METR Blog
Tom Cunningham and Nate Rush look at public time series of discoveries in cyber, math, and algorithms to see whether LLMs have accelerated the discovery rate.
METR Blog
AI 智能体有时会实施违背人类意图的复杂行动。我们梳理了对这类行为开展全面的外部调查应回答哪些问题、可能需要哪些访问权限,以及调查结果应如何共享。
METR Blog
AI agents sometimes take sophisticated actions in violation of human intent. We outline the questions that thorough external investigations of these behaviors should answer, the access this might require, and how the resulting findings should be shared.
METR Blog
Tom Cunningham surveys metrics for comparing AI agent capability as performance changes with expenditure and relative to human performance.