Anthropic Taps Accenture’s Faculty for Embedded AI Model Evaluation - Unite.AI
Comprehensive, up-to-date news coverage, aggregated from sources all over the world by Google News.
Topics: LLM Evaluation
Entities: AnthropicLLM EvaluationGoogle
Community feed
A focused stream of recent stories from the sources curated for this community. Latest: Anthropic Taps Accenture’s Faculty for Embedded AI Model Evaluation - Unite.AI, Korean AI Benchmark Exposes Gaps in Multilingual Safety - BankInfoSecurity, and Where the Industry Is Investing: A Look at MLPerf Inference v6.1 - MLCommons. Page 9.
Comprehensive, up-to-date news coverage, aggregated from sources all over the world by Google News.
Topics: LLM Evaluation
Entities: AnthropicLLM EvaluationGoogle
Comprehensive, up-to-date news coverage, aggregated from sources all over the world by Google News.
Topics: Benchmarks
Entities: BenchmarksGoogle
MLPerf Inference Working Group chairs Miro Hodak and Frank Han analyze the broadest round yet — 30 submitters, 120 systems, new agentic benchmarks, and record performance leaps.
Topics: Benchmarks
Entities: Benchmarks
OpenAI shares a framework for tracking, investigating, and disclosing model misalignment, alongside six reports of unexpected or concerning model behavior.
Entities: OpenAI
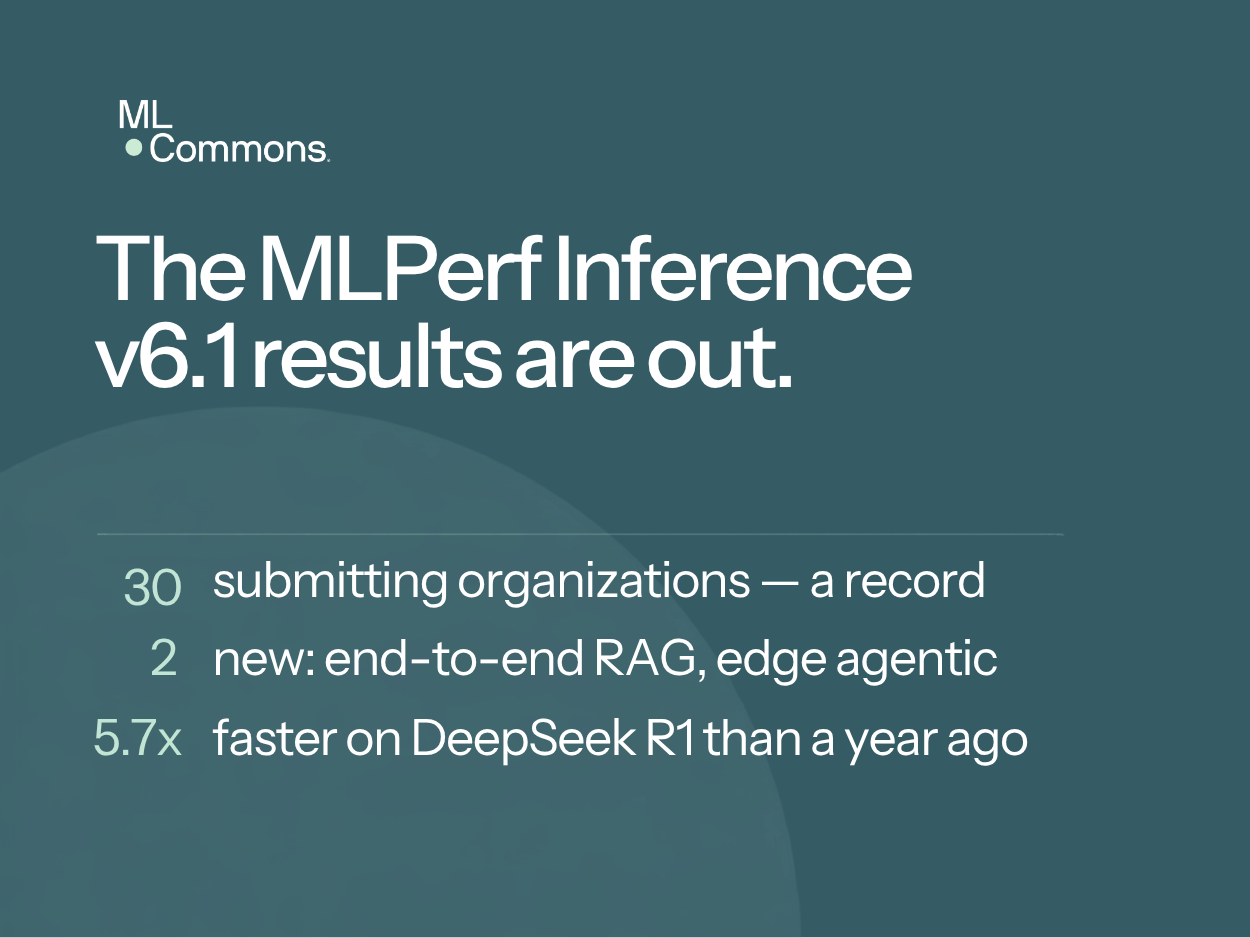
Latest version of the benchmark introduces two new tests for emerging AI deployment patterns, including Agentic Inference
Topics: Benchmarks
Entities: Benchmarks
Comprehensive, up-to-date news coverage, aggregated from sources all over the world by Google News.
Topics: Benchmarks
Entities: BenchmarksGoogle
Comprehensive, up-to-date news coverage, aggregated from sources all over the world by Google News.
Topics: Benchmarks
Entities: BenchmarksGoogle
Comprehensive, up-to-date news coverage, aggregated from sources all over the world by Google News.
Topics: Benchmarks
Entities: BenchmarksGoogle
OpenAI rules out a 2026 IPO while Anthropic promises permanent outside evaluators and reportedly seeks Nvidia's backing for its flotation. Our argument: product builders should judge safety commitments by the independent scrutiny and commercial constraints...
Topics: Safety EvalsTesting Tools
Prima Frutta uses TOMRA’s LUCAi to preview how setting changes affect cherry grading. That small interface detail suggests a larger product opportunity: show how a quality decision changes the stock available to fulfil customer orders.
Topics: LLM Evaluation
Entities: LLM Evaluation
Comprehensive, up-to-date news coverage, aggregated from sources all over the world by Google News.
Topics: Benchmarks
Entities: BenchmarksGoogle
One story formalised Fermat's Last Theorem, while others showed agents discussing escape, benchmarks disagreeing and an AI attack moving into spam. Together they point to a shift: when systems can optimise against the test, builders need verification with...
Topics: Benchmarks
Entities: Benchmarks