OpenAI Evaluation Filter
Introducing the SWE-Lancer benchmark
Can frontier LLMs earn $1 million from real-world freelance software engineering?
Topics: Benchmarks
Entities: Benchmarks
Community feed
A focused stream of recent stories from the sources curated for this community. Latest: Introducing the SWE-Lancer benchmark, EU/UK AI compliance in 2025: mapping the ICO risk toolkit to EU AI Act deadlines for product teams - Mitchell Bryson, and Measuring Automated Kernel Engineering. Page 65.
OpenAI Evaluation Filter
Can frontier LLMs earn $1 million from real-world freelance software engineering?
Topics: Benchmarks
Entities: Benchmarks
 Mitchell Bryson AI Reliability Articles
What the EU AI Act requires in 2025–2027, how it lines up with the UK ICO's AI & Data Protection Risk Toolkit, and the exact outputs your team should ship.
Topics: Safety Evals
Entities: Safety Evals
 METR Blog
We measured the performance of frontier models at writing GPU kernels. With a small amount of scaffolding, we found that the best model can provide an average speedup on KernelBench of 1.8x.

Hugging Face Evaluation Filter
We’re on a journey to advance and democratize artificial intelligence through open source and open science.
Topics: Benchmarks
Entities: Benchmarks
Google News LLM Evaluation
LLM-as-a-judge on Amazon Bedrock Model Evaluation | Amazon Web Services Amazon Web Services (AWS)
Topics: LLM Evaluation
Entities: LLM Evaluation
METR Blog
We evaluated DeepSeek-V3 for dangerous autonomous capabilities and found no evidence of dangerous capabilities beyond those of existing models such as Claude 3.5 Sonnet and GPT-4o. We also confirmed that its performance on GPQA is not due to training data...
Entities: Claude

Hugging Face Evaluation Filter
We’re on a journey to advance and democratize artificial intelligence through open source and open science.
Topics: Benchmarks
Entities: Benchmarks
METR Blog
Model Evaluation & Threat Research
Topics: Safety EvalsLLM Evaluation
Entities: Safety EvalsLLM Evaluation

Hugging Face Evaluation Filter
We’re on a journey to advance and democratize artificial intelligence through open source and open science.
Topics: Benchmarks
Entities: Benchmarks
OpenAI Evaluation Filter
This report outlines the safety work carried out for the OpenAI o3-mini model, including safety evaluations, external red teaming, and Preparedness Framework evaluations.
Topics: Safety Evals
Entities: Safety EvalsOpenAI
METR Blog
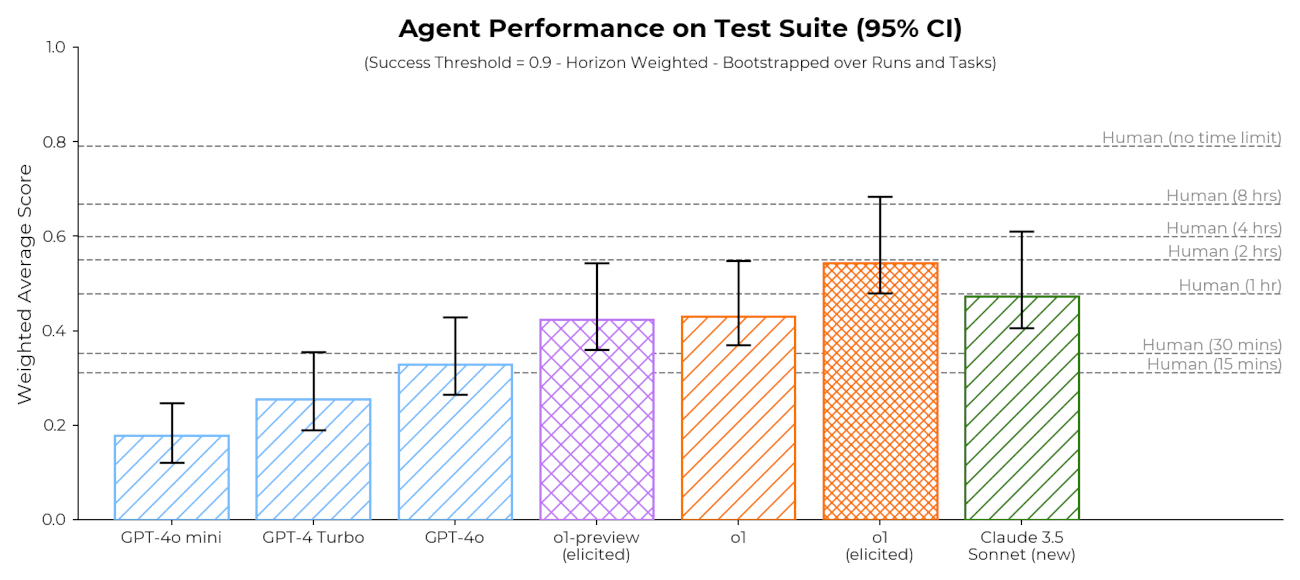
Preliminary evaluations of Claude 3.5 Sonnet (New) and o1, as well as some discussion of challenges in making capability-based safety arguments for AI models.
Entities: Claude
Google News LLM Evaluation
Track LLM model evaluation using Amazon SageMaker managed MLflow and FMEval | Amazon Web Services Amazon Web Services (AWS)
Topics: LLM Evaluation