Viteval | Next generation LLM evaluation framework powered by Vitest.
Next generation LLM evaluation framework powered by Vitest.
Topics: LLM EvaluationTesting Tools
Entities: Testing ToolsLLM Evaluation
Community feed
A focused stream of recent stories from the sources curated for this community. Latest: Viteval | Next generation LLM evaluation framework powered by Vitest., Research Update: Algorithmic vs. Holistic Evaluation, and Notes on Scientific Communication at METR. Page 61.
Next generation LLM evaluation framework powered by Vitest.
Topics: LLM EvaluationTesting Tools
Entities: Testing ToolsLLM Evaluation
Many AI benchmarks use algorithmic scoring to evaluate how well AI systems perform on some set of tasks. However, AI systems often produce code that scores well but isn't production-ready due to issues with test coverage, formatting, and code quality. This...
Topics: BenchmarksLLM Evaluation
Entities: BenchmarksLLM Evaluation
How we think about tradeoffs when communicating surprising or nuanced findings.
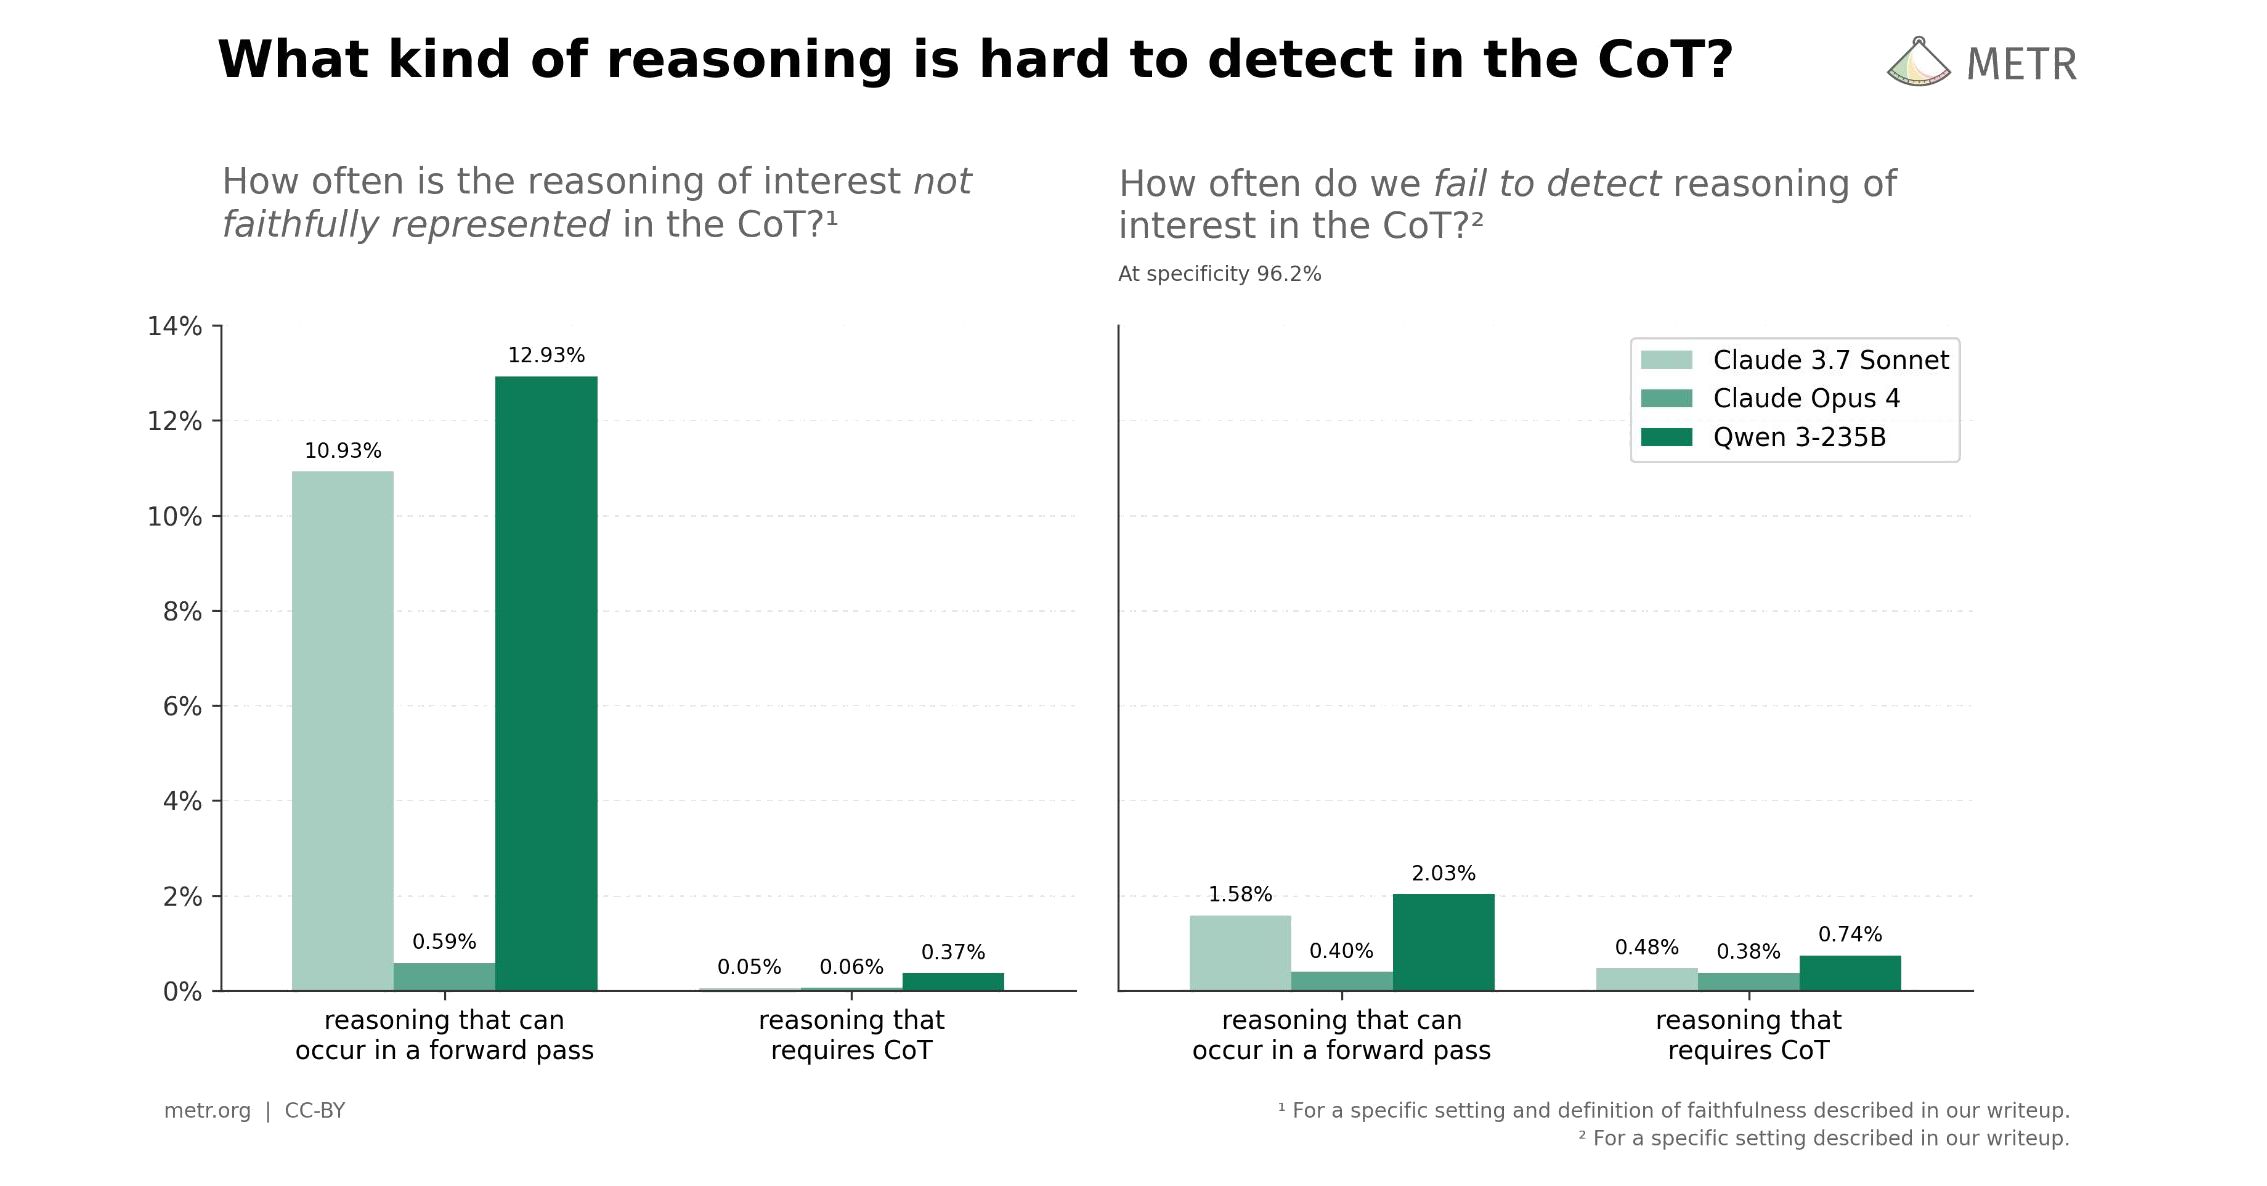
Recent work from Anthropic and others claims that LLMs' chains of thoughts can be “unfaithful”. These papers make an important point: you can't take everything in the CoT at face value. As a result, people often use these results to conclude the CoT is...
Entities: Anthropic
We evaluate whether GPT-5 poses significant catastrophic risks via AI self-improvement, rogue replication, or sabotage of AI labs. We conclude that this seems unlikely. However, capability trends continue rapidly, and models display increasing eval awareness.
Topics: LLM Evaluation
Entities: LLM EvaluationOpenAI
Is your AI benchmark lying to you? Nature
Topics: Benchmarks
Entities: Benchmarks
A Blog post by Technology Innovation Institute on Hugging Face
Topics: Benchmarks
Entities: Benchmarks
MLPerf Client 1.0 AI benchmark released — new testing toolkit sports a GUI, covers more models and tasks, and supports more hardware acceleration paths Tom's Hardware
Topics: BenchmarksTesting Tools
Entities: BenchmarksTesting Tools
Impact of agricultural industry transformation based on deep learning model evaluation and metaheuristic algorithms under dual carbon strategy Nature
Topics: LLM Evaluation
Entities: LLM Evaluation
Discover how Intercom built a scalable AI platform with 3 key lessons—from evaluations to architecture—to lead the future of customer support.
This new AI benchmark tests how much AI sucks up to you fanaticalfuturist.com
Topics: Benchmarks
Entities: Benchmarks
German Gov-Backed AI Benchmark Tracks Large Language Models in 200 Languages Slator
Topics: Benchmarks
Entities: Benchmarks