Meta's Muse Spark edges past Google's Gemini on AI benchmark - The Economic Times
Meta's Muse Spark edges past Google's Gemini on AI benchmark The Economic Times
Topics: Benchmarks
Entities: BenchmarksGeminiGoogle
Concept
Meta's Muse Spark edges past Google's Gemini on AI benchmark The Economic Times
Topics: Benchmarks
Entities: BenchmarksGeminiGoogle
New AI Benchmark Holds GPT-5.5 at 43% on Cross-Domain Reasoning Chains Tech Times
Topics: Benchmarks
Entities: Benchmarks
AI Benchmark Digest — 2026-07-20 Buttondown
Topics: Benchmarks
Entities: Benchmarks
Kimi K3 tops AI benchmark in a first for Chinese models Notebookcheck
Topics: Benchmarks
Entities: Benchmarks
Kimi K3 Highlights Limits of AI Benchmark Leaderboards BankInfoSecurity
Topics: Benchmarks
Entities: Benchmarks
PsyEval: a comprehensive large language model evaluation benchmark for mental health | npj Mental Health Research Nature
Topics: BenchmarksLLM Evaluation
Entities: BenchmarksLLM Evaluation
OpenAI's GPT-5.6 Sol tops AI benchmark for pres... Pluang
Topics: Benchmarks
Entities: BenchmarksOpenAI
DevRev Open Sources Enterprise AI Benchmark Open Source For You
Topics: Benchmarks
Entities: Benchmarks
MLCommons introduces a new Edge Agentic Inference benchmark for MLPerf Inference v6.1, targeting multi-turn tool-calling LLMs on a single edge accelerator. Submit by July 31, 2026.
Topics: Benchmarks
Entities: Benchmarks
Sourcetable Humiliates Microsoft Copilot and Google Sheets in New AI Benchmark AiThority
Topics: Benchmarks
Entities: BenchmarksGoogleMicrosoft
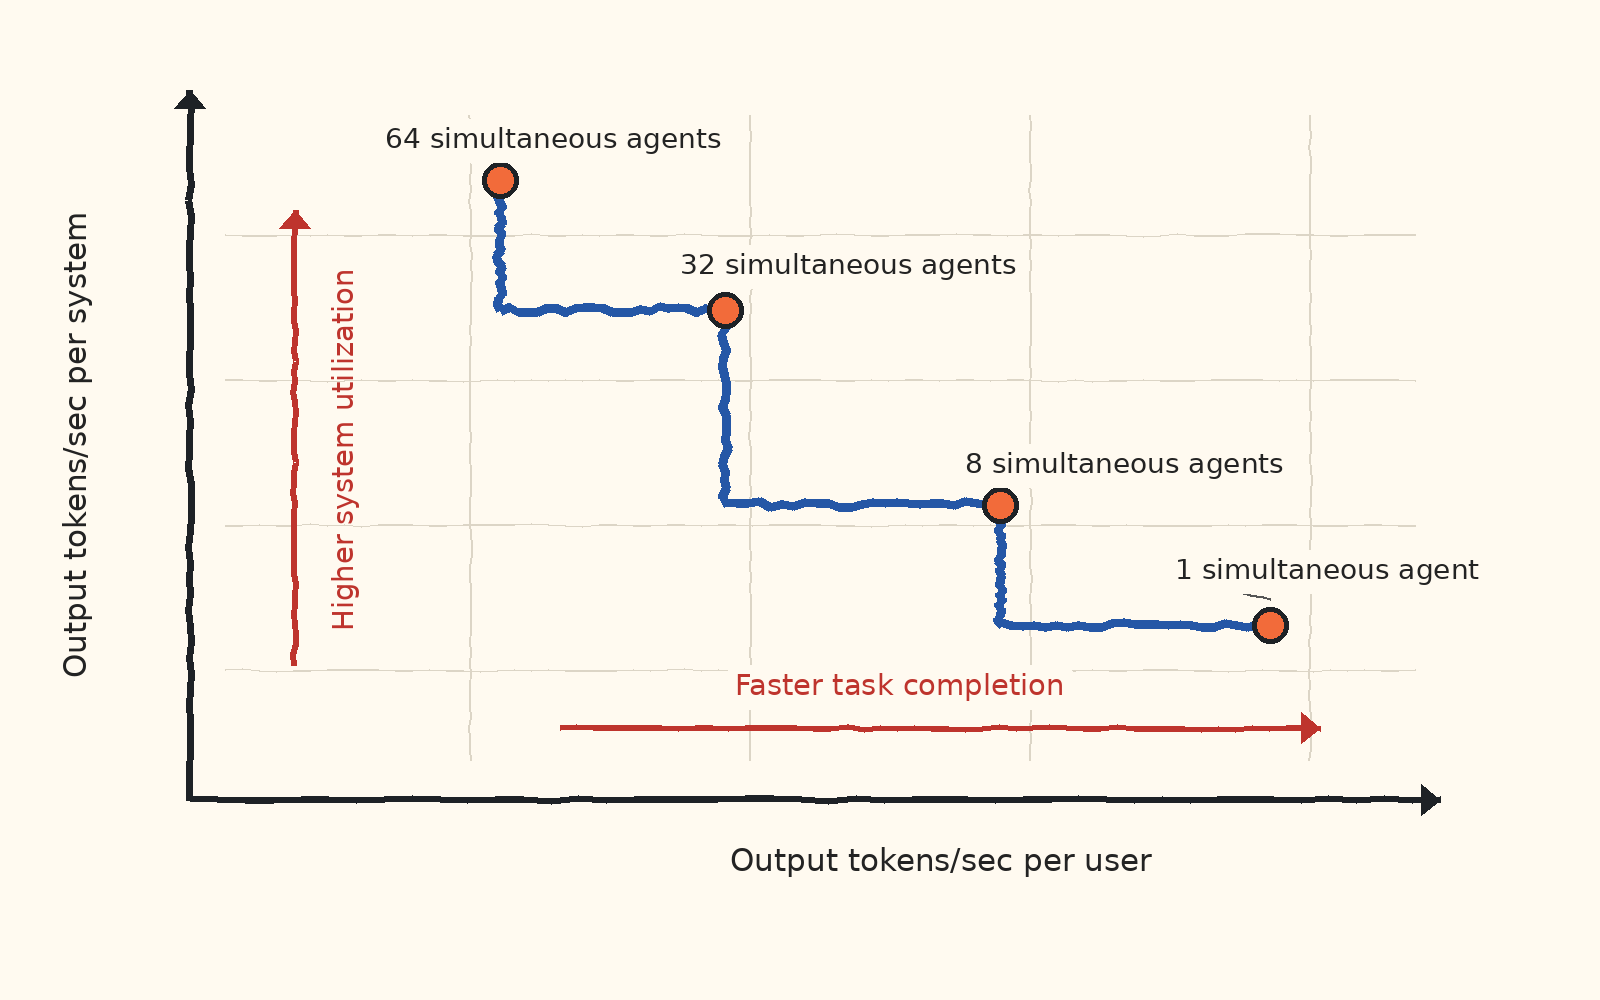
MLCommons introduces a new multi-turn benchmark for measuring LLM serving systems under growing context and closed-loop agent workflows. Featuring Kimi K2.6 and Qwen3.6-35B-A3B. **Category:** Benchmarks, LLM, Agentic AI, Inference
Topics: Benchmarks
Entities: Benchmarks
A new analysis from OpenAI reveals issues in SWE-Bench Pro, a popular coding benchmark, raising concerns about reliability and accuracy in evaluating AI models.
Topics: BenchmarksTesting Tools
Entities: BenchmarksTesting ToolsOpenAI