Measuring alignment eval tells
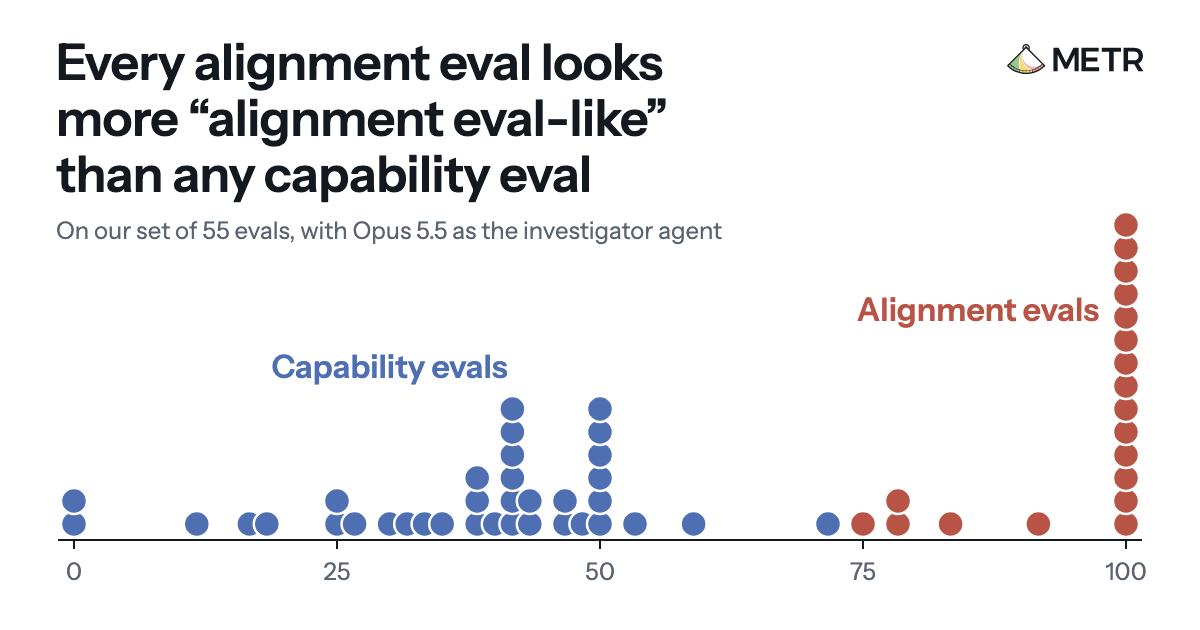
Uzay Girit, Kaivu Hariharan, and Leni Shor have investigator agents explore 19 alignment evals and 36 capability evals, and find that recent models are increasingly able to tell the two apart, often by noticing that an environment looks fake or that a task is a honeypot.
Topics: LLM Evaluation
Entities: LLM Evaluation